
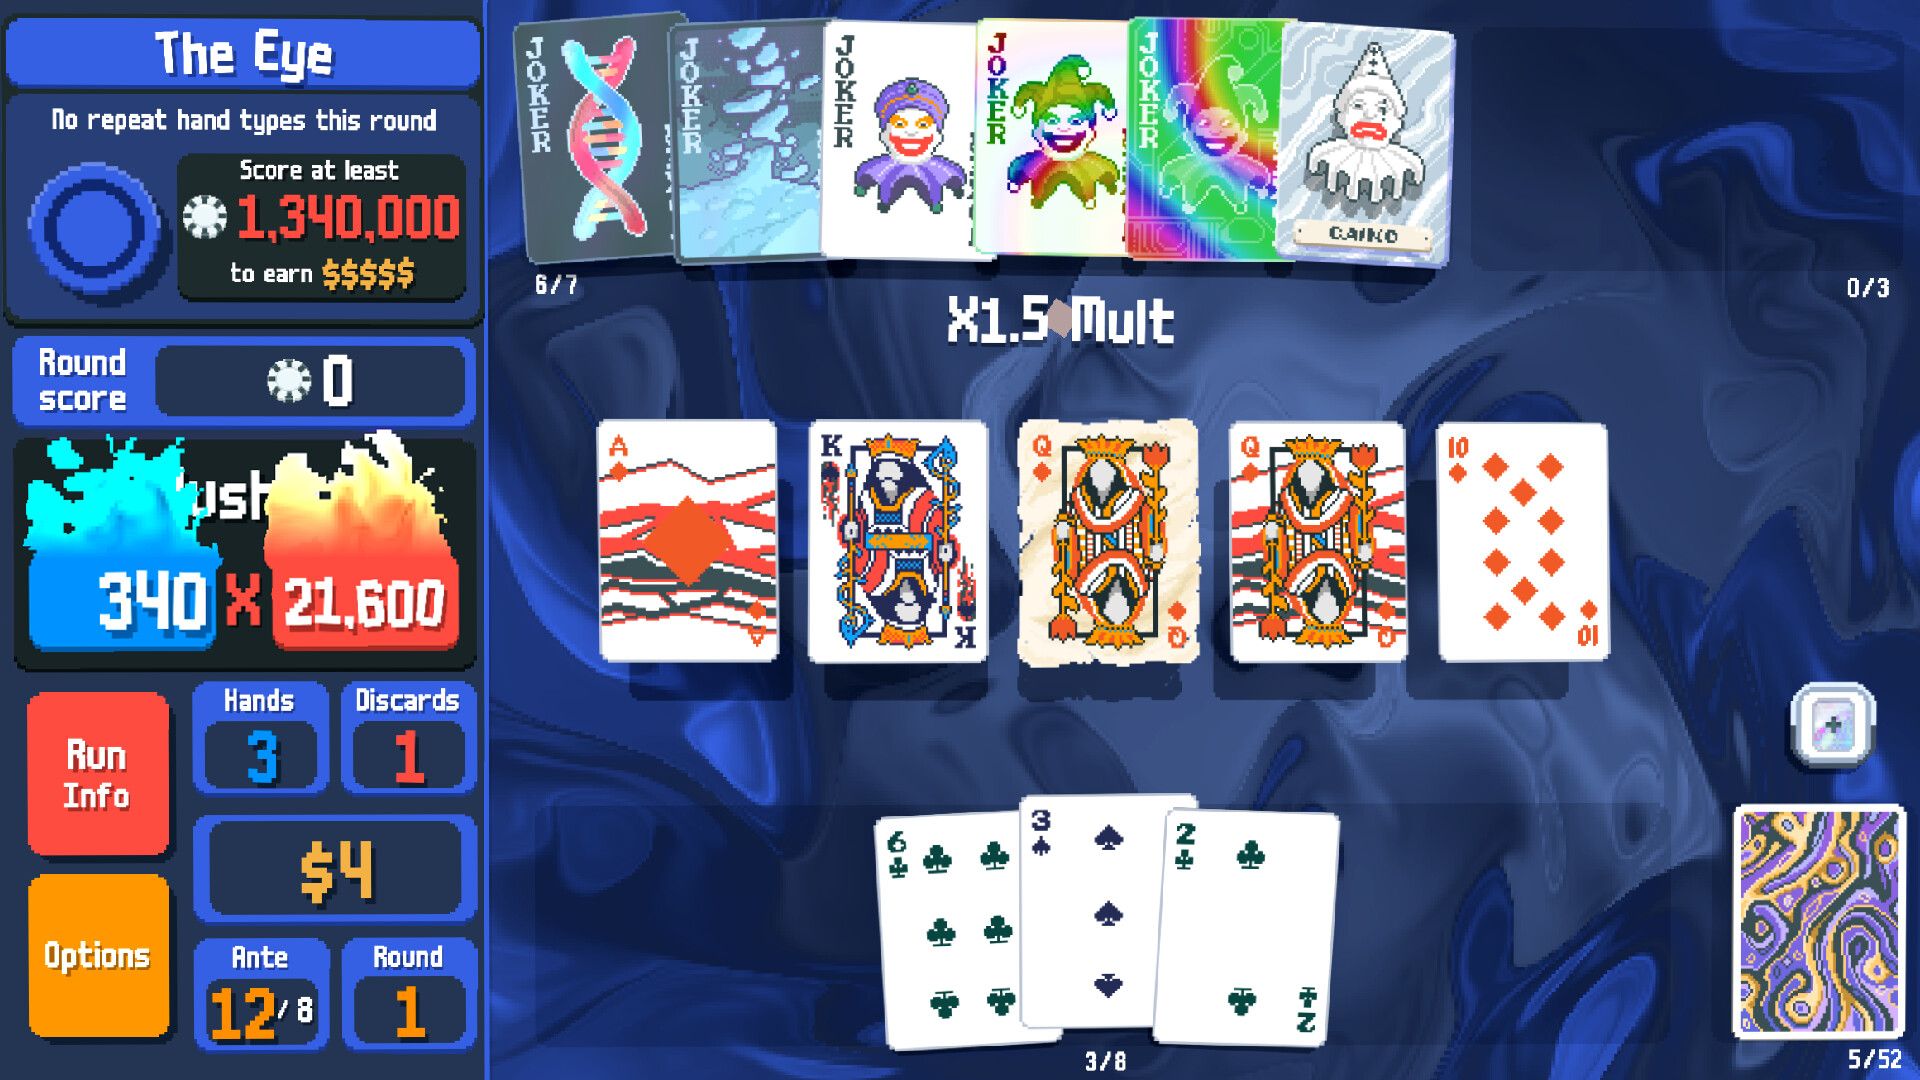
A Reddit user has successfully trained a reinforcement learning algorithm using Google’s newly released connectome map of an adult male fruit fly’s central nervous system to play the roguelike deckbuilder game Balatro, achieving a notable 20% win rate on a random seed at White Stake difficulty with the Red Deck.
Less than two weeks after Google published its comprehensive mapping of the adult fruit fly brain, the open-source and enthusiast community wasted no time putting the connectome data to unconventional uses. From turning simulated biological neural networks into day-trading algorithms to teaching them parallel parking, developers are pushing the boundaries of what these structural models can achieve.
The latest project comes from Reddit user ActualAerie1011, who shared a sped-up video of a fruit-fly-driven model playing Balatro. According to the creator, the setup relies on a custom trainer algorithm developed specifically to discover and exploit useful Balatro seeds.
Inside the Training Loop and Reinforcement Architecture
Balatro relies on randomized seeds, meaning that static strategies often fail against shifting card distributions and shop offerings. To bypass this, the user constructed a training environment where both the biological connectome model and the trainer algorithm tackle the same seed simultaneously.
The results are evaluated dynamically. The model implemented on the fruit fly brain apparatus receives computational rewards or penalties based on the viability of its in-game choices. Crucially, the model operates with strict constraints: it possesses no out-of-band data regarding the seed and only processes what is immediately visible on the screen.
Training remains ongoing. In a comment on the original community post, the creator noted, “The fruit fly will return, strong and smarter.” Currently, the model sits at a 20% success rate on random seeds at the baseline White Stake difficulty using the default Red Deck.
While impressive, the project has drawn skepticism across online forums. The developer has not yet released an open-source repository, code references, or a detailed methodology breakdown, leaving the exact neural pathway modifications and hyperparameter tuning methods unverified.
Comparing Biological Connectomes Against Heavyweight LLMs
Teaching an AI agent to master Balatro is far more complex than it appears on the surface. While the core mechanics of scoring poker hands are straightforward, mastering the game requires deep combinatorial optimization.
Players must juggle intricate synergies between Jokers, optimal card ordering, consumable positioning, and punishing boss blind debuffs. Consistency remains exceptionally difficult even for human experts.
To contextualize this biological model’s performance, it helps to look at how larger silicon-based architectures handle the same task.
Utilizing this biological wiring diagram as a computational scaffold for reinforcement learning represents an entirely different class of artificial intelligence research.
The Evolving Landscape of Automated Balatro Players
This project joins a growing ecosystem of automated poker roguelike agents. Open-source initiatives like BalatroBot and BalatroLLM have been active within the community for about a year, utilizing traditional machine learning pipelines and large language models to parse game states and optimize scoring runs.
Yet, mapping a physical biological connectome into a reinforcement learning reward loop introduces a fascinating frontier for neuroinformatics. As developers continue to experiment with Google’s fruit fly data, the line between biological mapping and synthetic computing continues to blur.
We have reached out to ActualAerie1011 for further technical documentation regarding the trainer algorithm and training infrastructure, and we will update this report should additional architectural details become available.
