
NVIDIA this week unveiled the DGX Spark HPC Developer Kit at SC26, the supercomputing conference running in Chicago, shipping a four-node cluster that lets researchers run models of up to 700 billion parameters right on their desk.
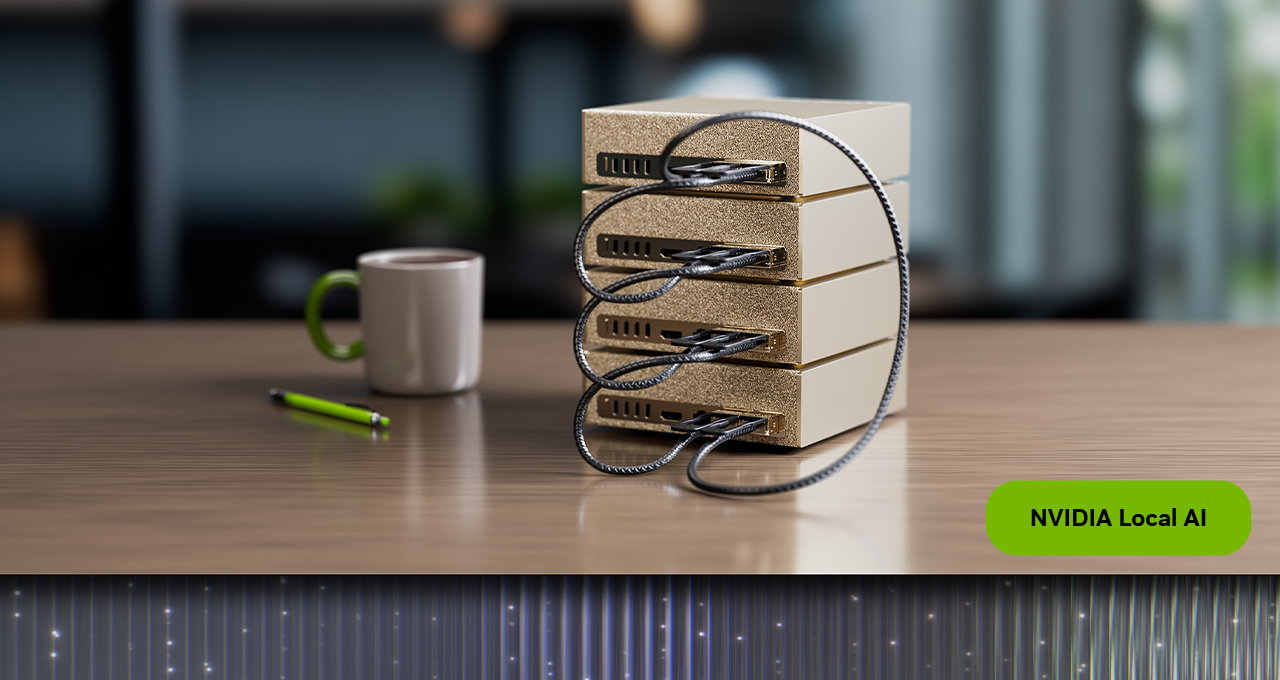
The kit links four GB10 Grace Blackwell Superchip systems — the chip that powers each DGX Spark — into a ring, with every node connected directly to its two neighbours over NVIDIA ConnectX-7 networking. There is no network switch to buy or set up, blogs.nvidia.com reported. Clusters can be scaled from one system to four.
At four nodes, the cluster provides 512GB of combined memory and 16TB of NVMe storage, according to blogs.nvidia.com. That’s where the two reports diverge: gpncentral.com puts the NVMe figure at 20TB. Either way, the box is meant to distribute models and scientific workloads across the cluster rather than squeeze them into a single node.
A supercomputing lab on your desk. ⚡ New at #SC26: the NVIDIA DGX Spark HPC Developer Kit, built for researchers, academics and developers. 🟢 Connect up to 4x DGX Spark systems in a ring over NVIDIA ConnectX-7 🟢 No network switch needed 🟢 Up to 512GB of memory pic.twitter.com/XisUR3ZOxg
With NVFP4 quantization, NVIDIA says researchers can deploy models with up to 700 billion parameters locally — DeepSeek V4.1 named as the example.
It’s less data vacuuming than advice: the sources say so, so the tape stays on, for now.
The pitch is about throughput of a different kind: researchers with fixed compute allocations no longer wait in a shared-GPU-cluster queue for every job. They can develop and debug on their own machines, keeping unpublished results and proprietary datasets on premises.
The economics, as the sources frame them: save server hours for production runs. Locality, not just compute.
One thing the buyer can’t get today, in either telling: the NVIDIA HPC SDK. NVIDIA says a playbook for it is “coming soon,” and that’s literal — the phrase appears in the announcement. The playbook will bring GPU-accelerated C, C++ and Fortran compilers, libraries and message passing interface tools, the same toolchain used on NVIDIA-powered supercomputers.
🧩NVIDIA introduced a 512GB desktop AI cluster designed to run models with up to 70B parameters locally – no switch needed. And you don't need a traditional GPU server rack. This is NVIDIA's new DGX Spark HPC Developer Kit. Announced at SC26. It's 4x DGX Sparks connected in a… pic.twitter.com/kXKYry06ly
NVIDIA lists its demonstrators: LAMMPS with Kokkos for materials simulation and NAMD for molecular dynamics, run on all four systems, plus community-validated standbys GROMACS, OpenFOAM for fluid dynamics, WRF for weather modeling, and NIM microservices OpenFold3 and Boltz-2 for biomolecular structure prediction.
The user stories skew heavily toward life sciences and academia. NVIDIA last week highlighted the Hartwig Group at UC Berkeley, whose researchers LoRA fine-tune the Nemotron 3 Super 120B-A12B architecture — a 120-billion-parameter chemistry model — and run eight- to 24-hour training fits back-to-back on a single Inamp专著7-6, avoiding the queue on their campus GPU cluster.
The Rubin Lab at UC Berkeley uses DGX Spark with Evo 2 for genomics; NVIDIA says its Forge Gateway benchmarks trained loss and task accuracy against a 155B-parameter comparison counterpart.
Not a bad bench given the SDK still can’t be installed yet.
