
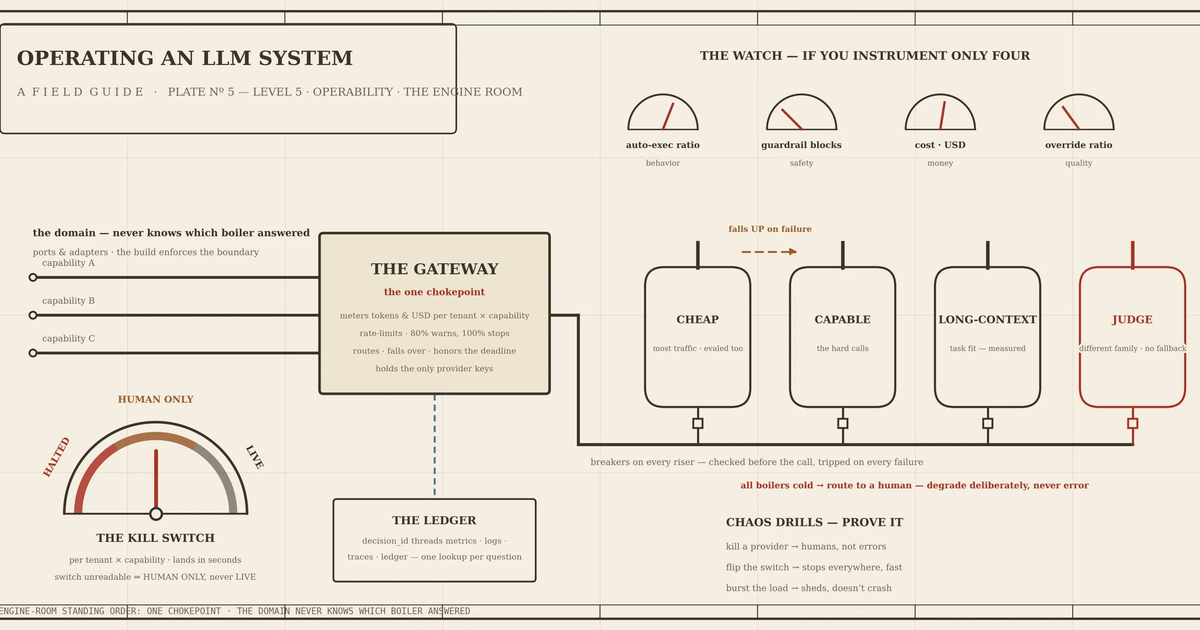
As large language model systems graduate from experimental chatbots to running daily workflows, maintaining control requires shifting focus from basic uptime to granular operability.
Establishing the AI-Specific Observability Stack
Traditional monitoring tools rely on request rates, latency, and CPU utilization to confirm a service is running. Production systems require a specialized observability architecture that combines standard metrics with a dedicated decision layer.
Every agent decision must be tracked as a first-class, measurable event. Metrics such as agent_auto_execution_ratio and agent_decision_confidence capture behavioral trends, while guardrail_blocks_total and judge_disagreements_total monitor safety layers.
Enforcing Cost Controls at the Gateway Chokepoint
Unmonitored LLM costs scale invisibly through unoptimized token counts, chatty prompts, retry storms, and unbounded agent loops. Discovering upside-down unit economics after the invoice arrives is an operational failure. Control requires routing every model call through a centralized API gateway where consumption is measured and restricted.
def complete(self, req: ChatRequest) -> ChatResponse:
    rate_limiter.check(req.tenant_id, est_tokens(req))
    resp = self._adapter.complete(req)
    metrics.incr("llm_tokens_total", resp.tokens_in, direction="in", tenant_id=req.tenant_id, model=req.model)
    metrics.incr("llm_tokens_total", resp.tokens_out, model=req.model, direction="out", tenant_id=req.tenant_id)
    metrics.incr("llm_cost_usd_total", cost(req.model, resp), capability=req.capability, model=req.model, tenant_id=req.tenant_id)
    return resp
Identifying Pipeline Performance Bottlenecks
| Inefficient Pattern | Optimized Architecture | Performance Impact |
|---|---|---|
| Nested O(n²) comparison loops | Indexed hash joins | Reduces 100M comparisons to ~20k operations |
| Per-record model requests | Batched calls or deterministic code rules | Eliminates redundant network round-trips |
| Unbounded serial pipeline stages | Bounded parallel concurrency | Aligns execution speed with true resource constraints |
Caching deterministic steps—such as embeddings and parsed inputs—further reduces unnecessary compute cycles. By pairing structural cost governance with rigorous pipeline profiling, engineering teams transition from hoping their LLM systems work to reliably operating them day-to-day.
