
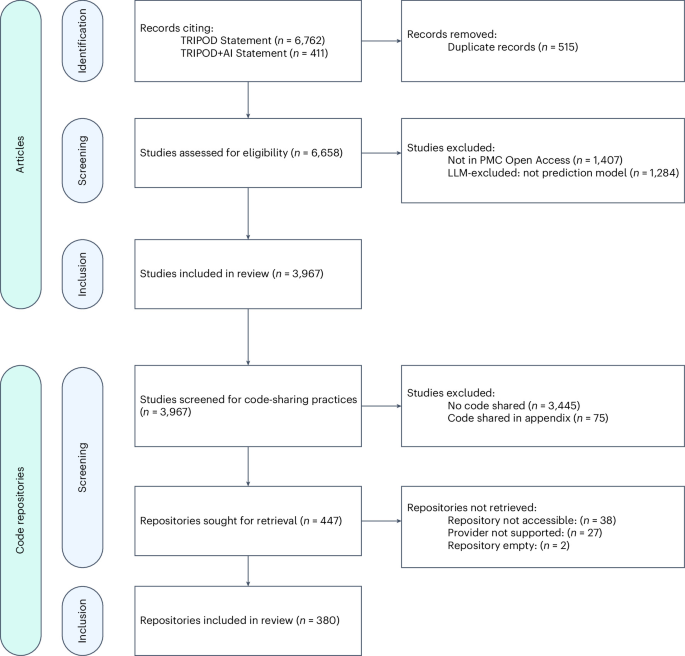
A scoping review reveals that a significant proportion of healthcare research papers citing the TRIPOD or TRIPOD+AI reporting standards fail to provide accessible analytical code, raising urgent questions about computational reproducibility in clinical prediction models.
As multivariable prediction models increasingly shape diagnostic and prognostic patient care, independent verification of underlying algorithms remains a critical bottleneck. A comprehensive scoping review utilizing advanced automated pipelines examined PubMed-indexed literature citing the TRIPOD and TRIPOD+AI reporting guidelines up to 11 August 2025 to measure true analytical code availability and structural quality.
- Multivariable Prediction Models: Mathematical equations combining two or more clinical predictors to estimate an individual’s probability of a current health condition or future medical outcome.
- Analytical Code Transparency: The practice of publishing the underlying statistical or machine-learning code alongside a research paper, allowing independent researchers to audit and replicate the findings.
- Automated Repository Auditing: The deployment of specialized large-language-model pipelines to scan for executable source files, license agreements, and software dependency files.
Automating Scoping Reviews for Code Transparency
To characterize code-sharing practices across modern medical literature, researchers designed a robust evaluation pipeline targeting all PubMed-indexed primary research articles citing the TRIPOD or TRIPOD+AI guidelines as of 11 August 2025. Restricting inclusion to articles retrievable through the PubMed Central Open Access API ensured full methodological reproducibility without subscription barriers. The investigation registered its protocol under identifier INPLASY202620080 in accordance with the PRISMA extension for scoping reviews.
Data analysis proceeded in two distinct phases: article-level screening and deep repository characterization. An automated pipeline driven by GPT-5.2 (2025-12-11) extracted metadata, determined eligibility, and identified code repositories. The automated system was validated against human-annotated subsets.
Structural Characteristics and Repository Documentation
Once identified, repositories were ingested using a custom retrieval utility that compiled file trees, README documents, and source scripts into structured text files. A secondary LLM assessment evaluated 14 specific features defined by the TRIPOD-Code executive committee, including software dependencies, licensing information, test frameworks, and random seed control for stochastic processes. Human validation across 35 retrieved repositories confirmed a weighted F1 score of 0.83.
| Evaluation Metric | Target Feature | Model Performance (F1 Score) |
|---|---|---|
| Repository Audit | Overall 14-Feature Evaluation | 0.83 Weighted F1 Score |
Future Trajectory of Clinical AI Governance
References
- PRISMA Extension for Scoping Reviews: Reporting guidance for systematic literature reviews.
- INPLASY Protocol Registry: Registration record INPLASY202620080.
- TRIPOD and TRIPOD+AI Statement Guidelines: Transparent reporting of a multivariable prediction model for individual prognosis or diagnosis.
