
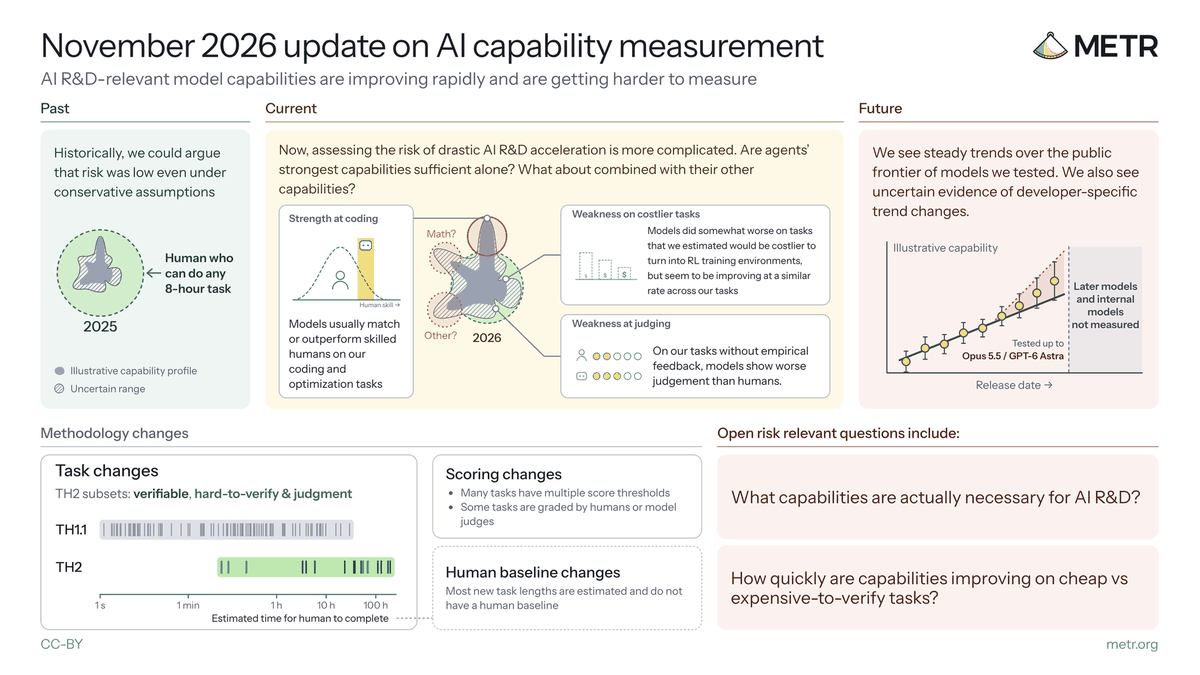
On November 20, 2026, METR reported that public frontier AI models’ 50% time horizons are doubling roughly every 110 days, while performance on open-ended research judgment tasks lags significantly behind.
The evaluation covered 15 major model checkpoints from GPT-4o and o1 through OpenAI’s GPT-6 Astra and Anthropic’s Claude Opus 5.5.
Verifiable Tasks Double Faster
On the TH2 verifiable subset alone, the estimated doubling time falls to 1.65 months. METR cautions this noisy result could reflect task composition or selection during development rather than broad acceleration.
Research Judgment Lags
Unlike the verifiable tasks, models lag substantially on these open-ended research and evaluation design challenges.
Flashback to June 14, 2024. At the time, frontier AI models have zero fluid intelligence. They score around 5% on ARC 1. They can't reliably add two numbers. They make laughable logic errors every other prompt. Reasoning models don't exist. Coding agents don't exist. Claude Code…
“The improvement we observe, I think that does tell us something for the current moment,” said Najoung Kim, a linguist and computer scientist at Boston University. “I'm not sure just yet how to think about how it would extrapolate.”
Human Calibration Relied on Researcher Estimates
Direct human baselines informed only 9% of human-duration estimates across the 34 newly calibrated tasks. Researchers defined score-and-time thresholds using successful human baselines for three tasks and researcher estimates for 31. Specialists evaluating tasks were paid $200–$350 per hour and could use Sonnet 5 for implementation.
Costlier Tasks Show Wider Gaps
Controlling for task length, METR found that higher Lifecycle Cost tasks—those more expensive to develop and run as containerized environments—were 2.9 times as expensive as lower-cost tasks on average. Models performed 2.9 times worse by time horizon, equivalent to 1.5 doublings.
Extrapolation Points to July 2027
A naive extrapolation would put 50% time horizons at the suite’s longest tasks—200 hours—in July 2027. METR emphasizes this is not a delivery promise.
Evaluation Scope Covers Latest Public Models
The evaluation presented evidence from capability assessments of public models relevant to AI research and development acceleration, up to Opus 5.5 and GPT-6 Astra. METR noted significant uncertainty about what capabilities are necessary for drastic acceleration and how quickly relevant model capabilities are improving. The progression toward TH2 marks a conceptual evolution in AI benchmarking, moving from code generation toward scientific autonomy.
We're sharing new data on how AI is changing research at OpenAI. We find researchers' AI use continues to rise exponentially, and agents are completing longer tasks, but human involvement remains central in research. Researchers are also spending more time on safety and…
TH2 Suite Contains 36 Tasks
The TH2 suite consists of 36 tasks grouped into 12 task families with two broad subsets. TH2 verifiable comprises eight families covering optimization, machine learning, puzzles, and games. TH2 hard-to-verify and judgment comprises four families covering conceptual reasoning, judgment, and hard-to-verify research. The new tasks do not cover as broad a range of general software engineering work as the TH1.1 suite, and many now have multiple score thresholds instead of just one.
METR uses an index called the METR Capability Index (MCI) to track frontier AI capabilities over the past few years based on Item Response Theory, a statistical modeling technique similar to the one underlying the Epoch Capabilities Index.

When tracking public model capabilities on a composite metric of model ability over time, METR does not see strong acceleration or deceleration in model ability over the public frontier with the models tested.
OpenAI Cites Delegation Changes
OpenAI said that changing success rates may reflect both capability improvements and researchers changing which tasks they delegate and how they use agents. Humans remain central to AI development and more delegation is not the same as handing over the research agenda.
METR, a nonprofit research institute based in Berkeley, California, was founded in December 2023 when ARC Evals — the evaluation division of the Alignment Research Center led by Paul Christiano — spun off as an independent 501(c)(3). Its CEO is Beth Barnes, a former OpenAI alignment researcher who left in 2022 to form ARC Evals.
We've been working on understanding model capabilities beyond what our prior time horizon tasks could capture. Today we’re sharing a research update. We find that AI R&D-relevant capabilities are improving rapidly and are getting harder to measure. pic.twitter.com/Z1iXyIjERy
The organization evaluates frontier models’ ability to carry out long-horizon, agentic tasks and has worked with leading AI companies on pre-deployment evaluations, including for OpenAI’s o3, o4-mini, GPT-4o and GPT-4.5 and Anthropic’s Claude models. Following the 2026 OpenAI agent cyberattacks, OpenAI invited METR to conduct an independent investigation; it published its report on agent behavior, reasoning and collaboration on August 26, 2026.
More Work Needed for Full Understanding
Matt Putz added that there is just such a lot more to be done to actually get a fuller understanding.
Earlier coverage: METR Finds AI's Exponential Gains Don't Extend to Judgment Tasks
