
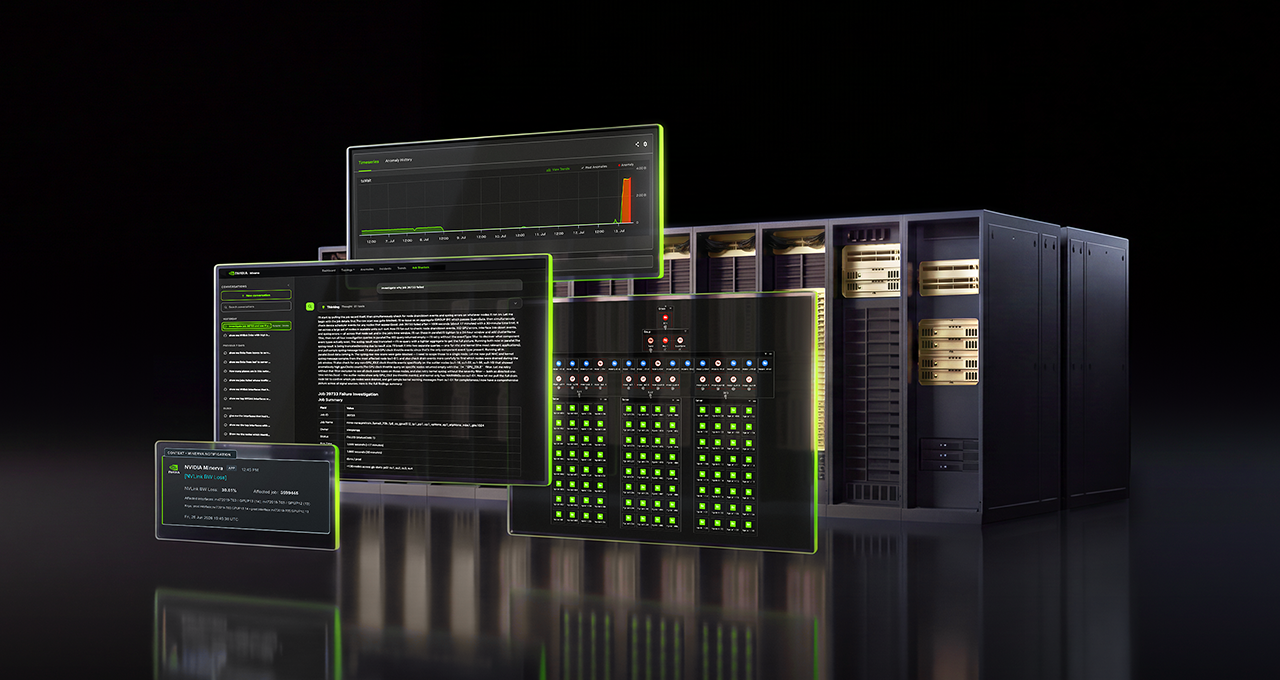
Built to help teams detect hardware degradation earlier, Minerva combines telemetry from diverse infrastructure and workloads, applying purpose-built machine learning models to maximize cluster yield, goodput, and uptime across hundreds of thousands of GPUs.
Mapping Complex AI Factory Workloads and Infrastructure
Modern AI infrastructure spans vast arrays of GPUs, high-speed networking switches, SuperNICs, storage drives, and job schedulers. Traditional monitoring tools isolate these components into separate silos for networking, compute, site reliability, and machine learning teams. Minerva bridges these isolated signals to build a dynamic knowledge graph that logically maps physical infrastructure alongside active jobs.
Operating at scale, a single degraded component like an overheating GPU or an NVMe drive losing performance under load can quietly bottleneck an entire training run. Minerva analyzes billions of data points every hour utilizing both supervised and unsupervised machine learning algorithms. The platform learns baseline behaviors, catches emerging anomalies, and correlates related events based on the underlying topology of the factory. Rather than overwhelming operators with a continuous flood of isolated alerts, Minerva groups an entire event storm into a single focused incident pointing directly to a likely root cause.
Native AI Assistance and Proactive Operations
The platform features a native AI assistant and hooks into external agentic AI tools, establishing a natural-language interface grounded in live telemetry. Operations teams can query cluster health and receive automated remediation recommendations directly through conversation. Engineers retain full control, choosing to manually implement fixes or connect Minerva to automated workflows via infrastructure application programming interfaces and external systems.
According to blogs.nvidia.com, this unified approach directly addresses key metrics that define AI factory yield:
We’re launching NVIDIA Minerva to bring end-to-end observability to AI factories at scale. The NVIDIA Minerva AIOps platform connects infrastructure and workload telemetry across GPUs, networking, storage, and schedulers, using AI to surface root causes and reduce alert noise… pic.twitter.com/YR4u3gdc9q
- Longer time between interruptions: Spotting trouble early allows long training jobs to run without unexpected downtime.
- Faster time to repair: Pinpointing the exact faulty component cuts down troubleshooting windows.
- Greater insight: Filtering a massive telemetry flood leaves only actionable alerts.
IREN and Other Partners Deploy Minerva to Optimize Factories
IREN is among the early partners deploying Minerva to optimize its AI factories. Denis Skrinnikoff, chief technology officer of IREN, noted that as they scale their infrastructure, maximizing GPU productivity is vital. Skrinnikoff stated via blogs.nvidia.com that NVIDIA Minerva gives their operations team one view across the network, GPUs, and active jobs, allowing them to focus on proactive maintenance rather than reactive troubleshooting.
Alongside IREN, Aolani, Bitdeer AI, IBM, Jio, Lambda, Quake AI, and Tesla plan to deploy the platform. On the hardware and systems integration side, Dell Technologies, Lenovo, and Supermicro will offer Minerva directly as part of their respective AI factory operations portfolios.
Keeping an AI factory running at full capacity starts with spotting issues before they cause a job to fail.NVIDIA Minerva brings together signals from across the stack to give operations teams fewer alerts, faster answers, and more productive GPU hours.Explore how it works in… pic.twitter.com/pP5FItbmtA
