
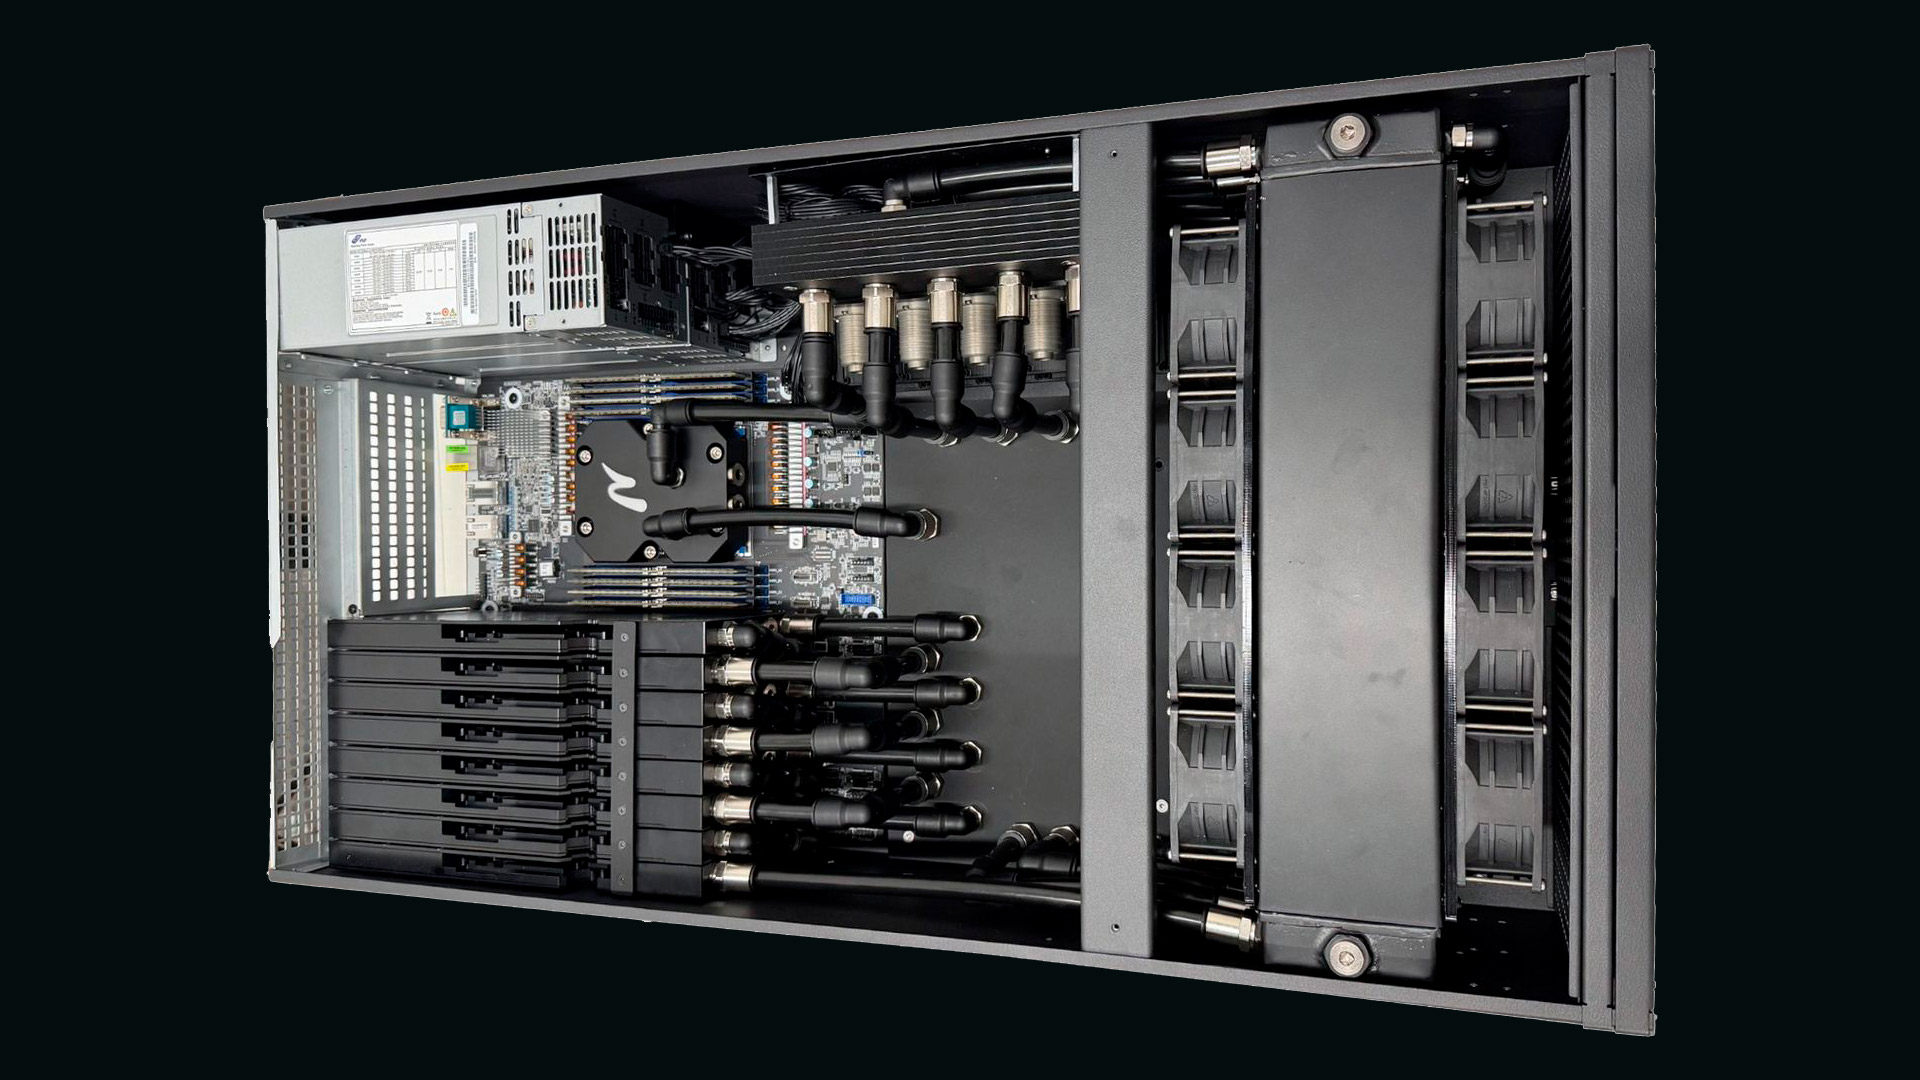
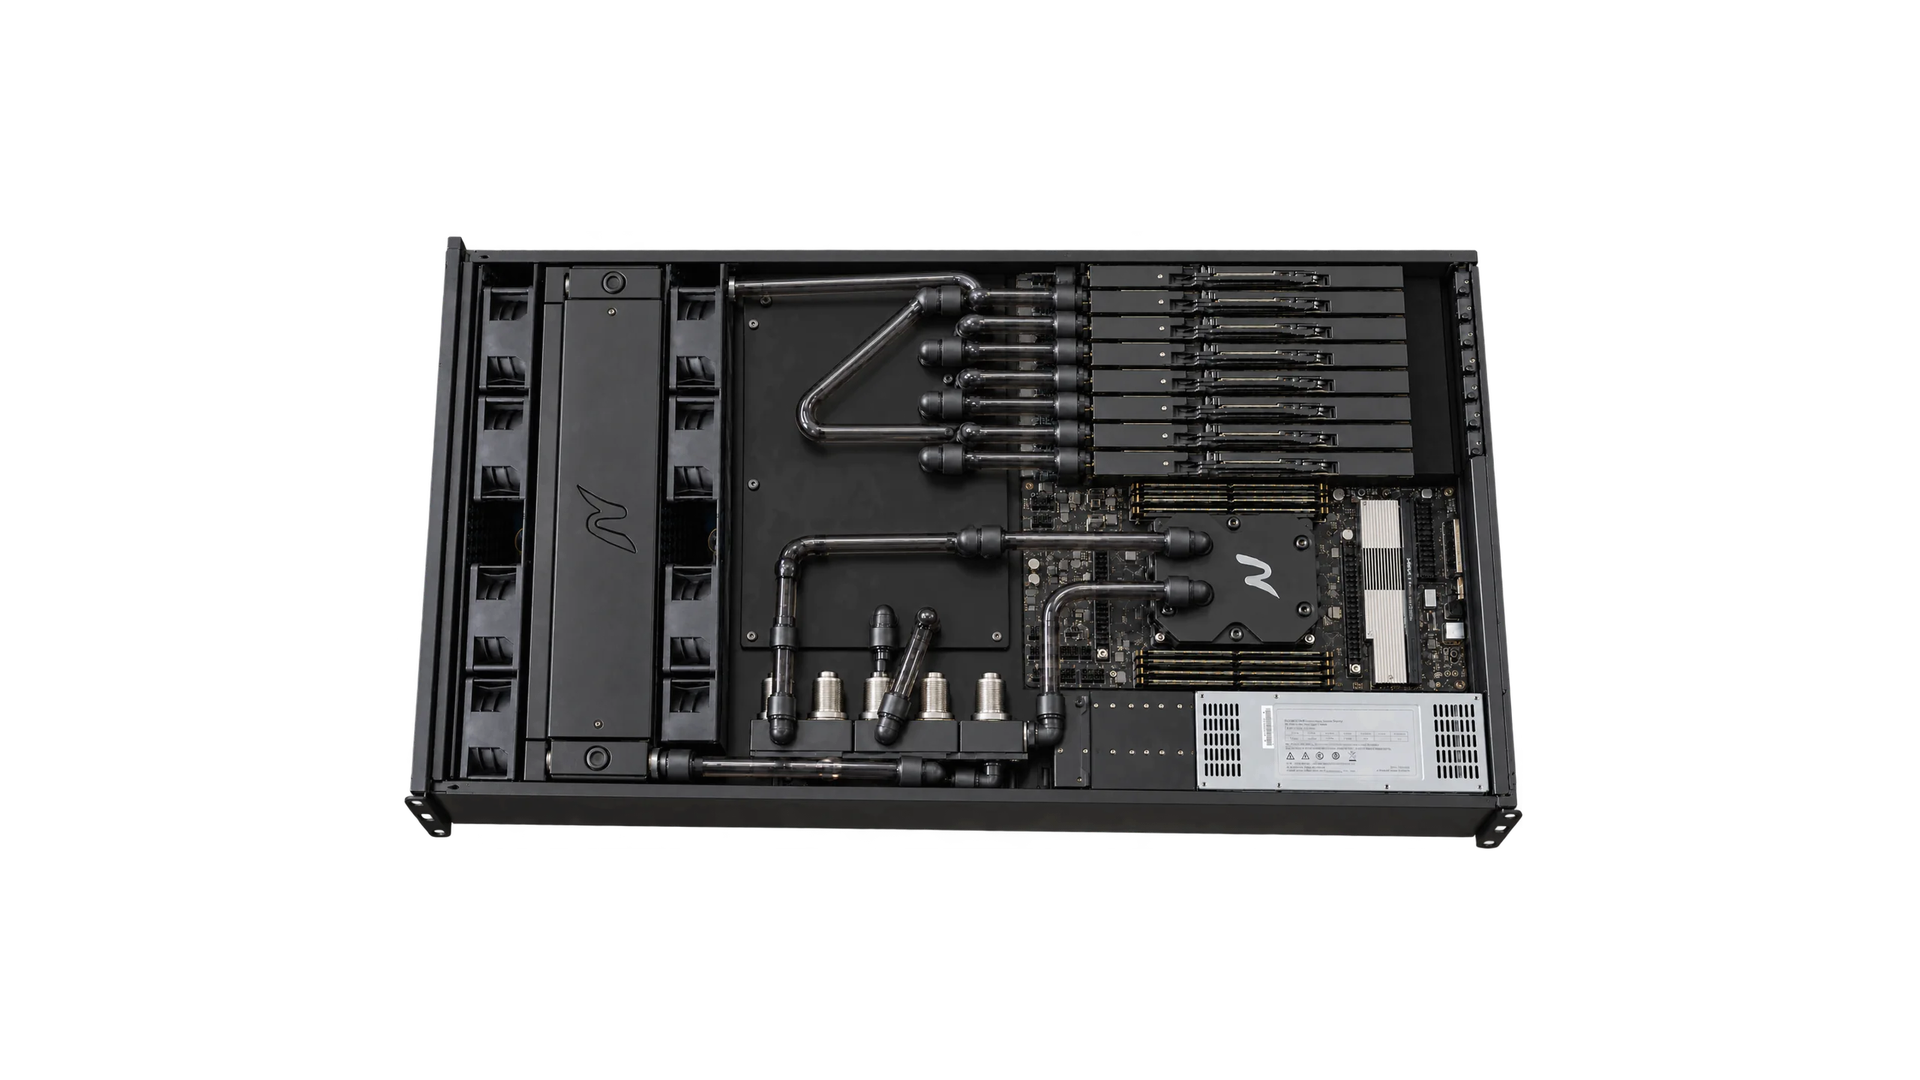
Eight liquid-cooled Nvidia RTX PRO 6000 Blackwell GPUs, each running at its full 600 watts, now fit inside a single 4U chassis that slots into a standard 19-inch air-cooled rack — no new piping, no facility rebuild.
That is the pitch behind the Renda Nova8, a liquid-cooled AI server launched this week by Renda and Irish thermal specialist Nexalus, and showcased at Data Centre World Paris on November 18–19, 2026, on the Arteco stand (G30).
The trick is mechanical. The RTX PRO 6000 Blackwell is normally a dual-slot card; the Nova8’s bespoke cooling design compresses each GPU into a single slot, which is how eight of them — 96 GB apiece — squeeze into 4U, AEC Magazine reported.
For operators whose facilities were never built for liquid cooling, that matters: the Nova8’s cooling loop is self-contained within the server, so a retrofit becomes a rack swap rather than a construction project.
The companies claim up to 20% greater AI throughput and 22% better energy efficiency than comparable air-cooled systems, with internal testing recording 55,000 tokens per second on a Llama 3.3 benchmark and an efficiency figure of 8.6 tokens per watt. Those are company claims, not independently verified results — a caveat unite.ai states plainly, noting the numbers “should not be read as guaranteed improvements for every workload.”
The engineering behind it is Nexalus’ patented jet-impingement cooling. Instead of pushing coolant along the channels of a conventional cold plate, the system fires jets of coolant onto a plate directly above each chip’s hottest zones, removing heat where it is generated.
That is what lets a CPU and eight full-power GPUs coexist in one 4U enclosure. The servers run their GPUs more than 20°C below maximum operating temperature, converting that thermal headroom into sustained performance rather than throttled bursts.
Why drop-in liquid cooling matters now
AI demand is growing faster than data centers can be rebuilt. Most operators cannot pause operations to rip out racks and install building-level coolant infrastructure — and the Nova8 is explicitly designed around that constraint, letting capacity be added within the racks, power and cooling a facility already has.
The system was co-developed and jointly patented by Renda and Nexalus, engineered end to end with GPUs, CPU, memory, storage, power and cooling specified and tuned as one system rather than assembled from parts.
Redundancy gets real numbers: 10 pumps and 16 fans, designed to maintain performance and reliability if a component fails. After-sales service runs globally through Nexalus partner UNICOM Engineering.
The thermal pedigree is unusual for a data center product. The same approach already cools high-density GPU servers for eight of the 11 constructors on the current Formula 1 grid, where teams use identical jet-impingement hardware.
“Formula 1 taught us that thermal management decides how much performance you can actually use, and AI is now facing the same challenge at data center scale,” said Ian “8Pack” Parry of RENDA, one of the world’s best-known hardware overclockers.
Parry’s background as an overclocker is not incidental. Extreme overclocking has always been a thermal problem disguised as a silicon problem — push a chip past its stock envelope and the limit you hit first is heat removal, not architecture. The Nova8 applies that lesson at rack scale: keep the die cool, and the silicon delivers its rated performance continuously instead of throttling under sustained AI load.

“Operators need more throughput, but most cannot pause to retrofit their facilities for liquid cooling,” said Kenneth O’Mahony, Chief Executive Officer of Nexalus. “Our patented, proprietary server design removes that barrier, bringing liquid-cooled performance into the racks they already run, with up to 20% more throughput and up to 22% greater energy efficiency.”
The numbers buyers should interrogate
| Metric | Figure | Context given |
|---|---|---|
| GPUs per chassis | 8 | Nvidia RTX PRO 6000 Blackwell, 96 GB each |
| GPU power draw | 600 W | Full rated capacity, all eight cards |
| Throughput | 55,000 tokens per second | Internal Llama 3.3 benchmark |
| Energy efficiency | 8.6 tokens per watt | Same rack footprint as comparison |
| Throughput gain | Up to 20% | Vs. comparable air-cooled systems |
| Efficiency gain | Up to 22% | Vs. comparable air-cooled systems |
unite.ai’s analysis is the sharpest skepticism in the coverage, and it is worth taking seriously. A throughput number alone does not establish what a production application will deliver.
Buyers should ask which model configuration, precision, input length, output length, concurrency and serving software produced the benchmark, and whether the reported power measurement covers just the server or a broader infrastructure boundary. Comparing unlike measurement boundaries can make a simple efficiency percentage misleading.
Latency matters too. An organization serving interactive requests will value predictable response time differently from one running large overnight batches — and both could run the same hardware while reaching different conclusions about cost and capacity.
How to test it before committing
The companies are offering a remote Test Drive on a Nova8 server to vetted, qualified organizations, letting customers run their own models before purchase. unite.ai suggests a sensible protocol for that trial: reproduce a representative workload, hold software settings constant, and compare against the existing deployment while recording power use, latency, throughput and sustained operation together.
That distinguishes a genuine infrastructure improvement from a benchmark advantage that never translates into the intended application.
Serviceability deserves equal attention in any liquid-cooled evaluation — how components are replaced, how the loop is maintained, and what a pump failure means for uptime. The 10-pump, 16-fan redundancy is the companies’ answer; the Test Drive is the place to verify it.
Nova8 solves facilities problem with liquid-cooled density
The Nova8 is not trying to out-innovate Nvidia’s roadmap — it is solving a facilities problem, which is arguably the more urgent one. The GPU is the same Blackwell silicon anyone can buy; the differentiation is thermals, integration and the promise that liquid-cooled density no longer requires liquid-cooled buildings. Whether the claims hold is exactly what the remote testing program exists to determine.
Qualified organizations can request a Test Drive through Nexalus and Renda, with the system on public display at Data Centre World Paris through November 19 on the Arteco stand (G30). O’Mahony’s framing of the bet, in the launch release carried by Business Wire via Morningstar and Yahoo Finance: the barrier to liquid cooling was never the chips — it was the building.
