
PrismML Shrinks Qwen to fit 8GB VRAM
In a personal technology column published on xda-developers.com, writer Sophie Lin explores the hardware limits of local artificial intelligence by replacing Qwen and Gemma models with Bonsai 27B, a heavily compressed large language model developed by startup PrismML that runs locally on an 8GB graphics card.
Hardware Limits of Local AI on Consumer GPUs
Running local AI models on an 8GB graphics card imposes a strict ceiling on available workflows and model sizes. Most newly released open-weight models exceed consumer hardware capacity, forcing users to rely primarily on models in the 4B to 9B parameter range. Throughout the year, Qwen 3.5 9B and Gemma 4 E4B filled this exact performance bracket. Attempting to run larger options usually results in memory spilling over into system RAM, causing a steep drop in generation speed. A standard 4-bit build of Qwen3.6 27B, for instance, requires more than double the available VRAM on an 8GB graphics card, keeping larger architectures out of reach for budget hardware setups.
Compression Architecture and Model Versions
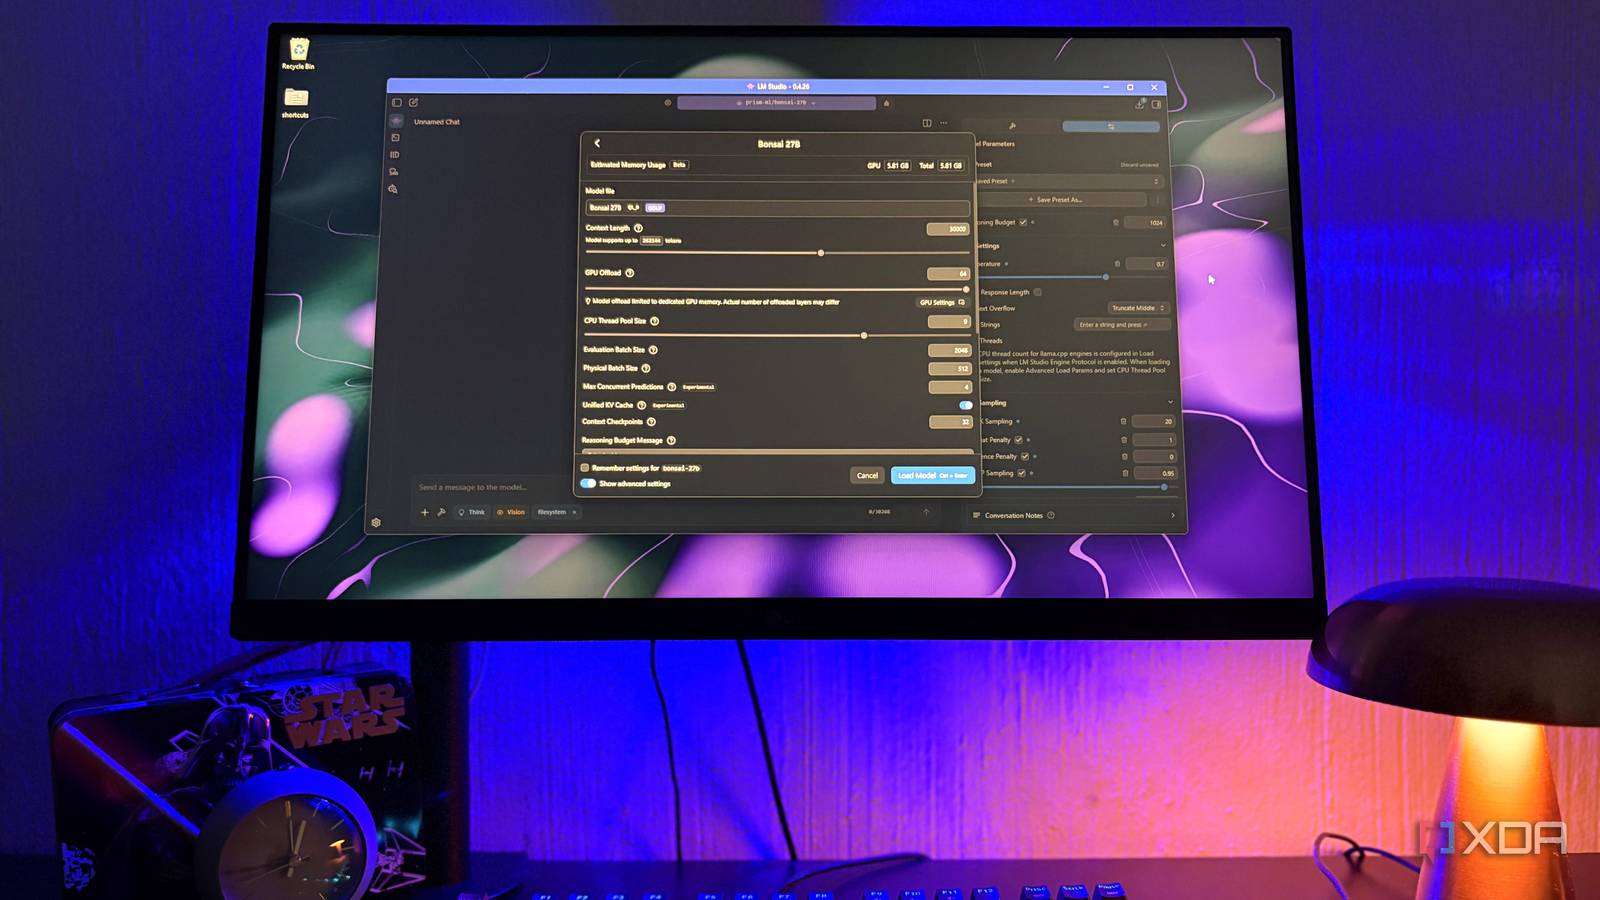
Bonsai 27B originates from PrismML, a startup born out of Caltech research, and uses Qwen3.6 27B as its architectural base. A full-precision 27B model typically exceeds 50GB, but PrismML compresses the architecture by storing every weight as either a +1 or a -1 alongside a shared scale value for each group of 128 weights, achieving an effective storage footprint of approximately 1.125 bits per weight. The startup distributes two separate builds. The original 1-bit version occupies just under 4GB of storage space. A newer iterative release, Bonsai 2, adopts a ternary structure by adding zero as a third possible value, though software runners such as LM Studio currently lack compatibility for these specific files. The writer utilizes the 1-bit Q1_0 Staff Pick build in LM Studio, which bundles vision files and totals 4.4GB—a footprint smaller than the Gemma 4 12B QAT.
Context Windows and Memory Management
Inheriting Qwen’s underlying architecture, Bonsai 27B supports a massive 262K-token context window. Because Qwen3.6 employs a lighter linear attention method, memory consumption during extended conversations scales significantly slower than in traditional architectures. Utilizing the full context window demands roughly 10GB of memory even with a compressed KV cache. Operating within an 8GB VRAM limit while reserving system headroom restricts active conversations to a limited context until memory exhaustion occurs.
Performance Across Math, Logic, and Coding Tasks
PrismML recommends specific sampling configurations for Bonsai 27B: a temperature of 0.7, top-p set to 0.95, top-k restricted to 20, with repeat and presence penalties disabled. Benchmark evaluations provided by PrismML score the model at 91.7 for mathematical reasoning, compared to 95.3 for the uncompressed Qwen baseline. Practical testing involving complex pricing logic and multi-bundle combinations demonstrated that the model evaluates every valid option correctly before selecting the cheapest alternative. Document summarization tasks yield clean, concise outputs without requiring document segmentation. Instruction-following capabilities remain robust despite aggressive compression, successfully adhering to multi-rule constraints regarding forbidden words and currency specifications. On HumanEval+, short coding tasks score 89.6 against 95.1 for full precision, though generated scripts can occasionally exhibit structural flaws, such as infinite file-monitoring loops.
Tool Calling and Image Processing Weaknesses
Compression compromises specific operational capabilities. Tool calling represents the model’s most significant performance deficit, with the 1-bit version dropping to 66.0 on PrismML’s agentic and tool-calling benchmarks—down from 80.0 for the uncompressed Qwen baseline. For heavy tool-use workflows, the writer continues to rely on Qwen 3.5 9B or Qwen 3.6-35B-A3B where hardware permits. Vision tasks also present limitations; while image analysis correctly identifies hex color values and dimensions, object lists can repeat multiple times or misinterpret specific element names as settings, leaving Gemma 4 the preferred alternative for image-centric workloads. Generation speed is slightly lower, producing 27 tokens per second on a pricing prompt compared to 35 tokens per second on Gemma 4 E4B under identical settings.
