
The University of Oxford has permitted OpenAI to train its artificial intelligence models on historical texts from the world-famous Bodleian Library. Uncovered through internal documents, the partnership reveals that digitized academic materials and rare historical collections are being fed into OpenAI systems to populate training sets and refine natural language processing capabilities.
As technology developers exhaust the digitally accessible corners of the internet, they are turning their gaze toward the physical archives of human history.
Inside the Oxford and OpenAI NextGenAI Partnership
The institutional relationship between the University of Oxford and the maker of ChatGPT officially began in March 2025. Initially, public announcements framed the collaboration around modernizing scholarship. Oxford stated that OpenAI software would be utilized to digitize texts from its monumental library, ensuring that fragile documents became more accessible to researchers and students worldwide.
However, internal meeting minutes obtained via freedom of information requests tell a more complex story. The documents confirm that the digitized Bodleian material has been directly integrated into OpenAI training sets. These systems analyze vast quantities of data to recognize linguistic patterns, teaching the software to construct complete sentences and execute complex cognitive tasks.
Here is why that matters for the broader information ecosystem. Scraped websites have grown increasingly saturated with synthetic, AI-generated content. The physical collections held within academic research libraries represent a reservoir of historical knowledge.
Managing Reputational Risk and Environmental Concerns
Not everyone inside the historic British university welcomed the arrangement. Meeting minutes from the Bodleian governance committee reveal sharp internal debates regarding the reputational hazards of partnering with a commercial artificial intelligence titan. Staff members also raised pointed questions about the environmental footprint of supporting an energy-intensive technology infrastructure.
Despite these internal reservations, university leadership has defended the scope and execution of the agreement. A University of Oxford spokesperson emphasized that the material processed through the project is modest in scale, strictly limited to out-of-copyright works, and shared on a non-exclusive basis. The Bodleian also retains full rights to the scans and has committed to publishing the digital assets openly online for public use within months.
An OpenAI spokesperson defended the initiative by highlighting the cultural necessity of historical preservation. With more than a billion people interacting with generative AI technology daily, company representatives argued that the underlying models must reflect diverse human histories, cultures, and perspectives rather than narrow digital silos.
Global Libraries Become the New Frontier for Tech Scavenging
Oxford is not acting in isolation. The institution stands as the sole United Kingdom member participating in OpenAI’s NextGenAI project. Similar access agreements have been struck across the Atlantic with prominent United States research institutions, including the Boston Public Library, the California Institute of Technology, the Massachusetts Institute of Technology, and the University of Michigan.
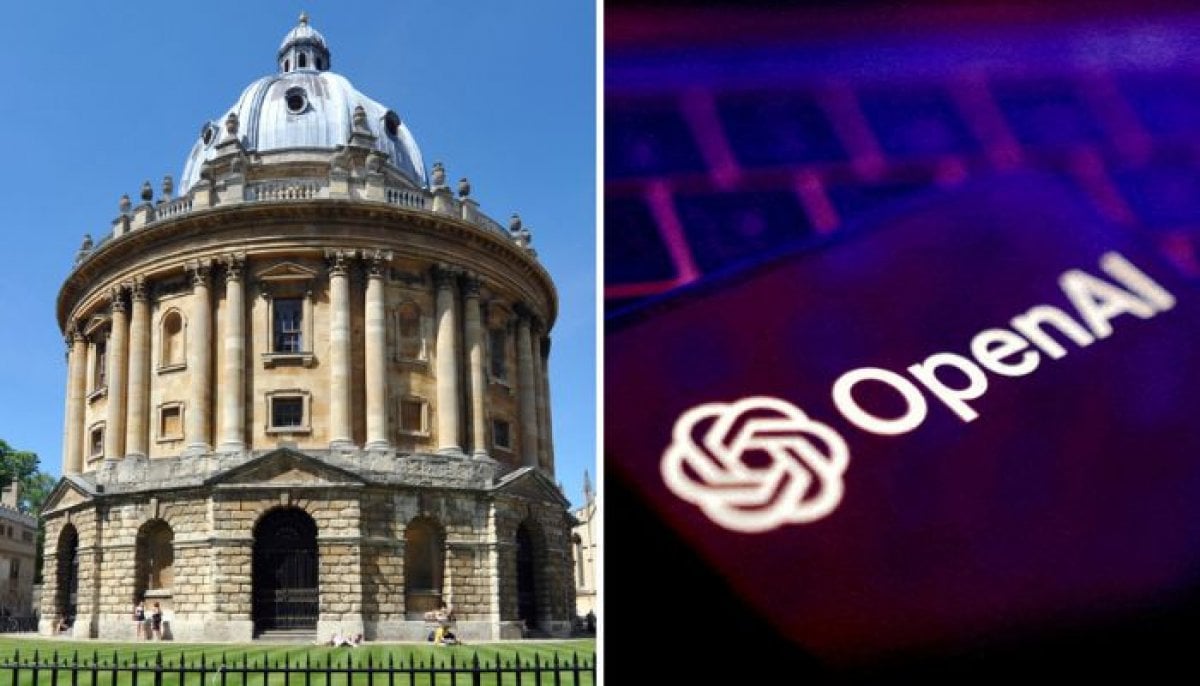
The scale of archival ingestion is sweeping. By June 2025, 125,000 images scanned from historical dissertations had been shared with OpenAI from the Bodleian collection. These documents include nineteenth and twentieth-century PhD theses from across Europe and North America. Other digitized artifacts include a rare collection of 10,000 sixteenth-century broadside ballads containing song lyrics and musical notes once circulated on Tudor street corners. Internal discussions have also touched upon the potential scanning of eighteenth-century Irish state papers, the private letters of novelist Marie Edgeworth, and Dorothy Hodgkin’s penicillin notebooks.
| Institution | Project Context | Material Scope |
|---|---|---|
| University of Oxford | NextGenAI (Sole UK Partner) | Historical dissertations, 16th-century ballads, out-of-copyright texts |
| Boston Public Library | NextGenAI Participant | Historical archives |
| Caltech & MIT | NextGenAI Participant | Institutional holdings |
| University of Michigan | NextGenAI Participant | Library and archival collections |
While the Bodleian has preserved its physical collections entirely intact—sidestepping the more aggressive acquisition tactics seen elsewhere in the industry—the wider marketplace for physical text is growing cutthroat. Secondhand booksellers have reported sudden, unusual spikes in orders for obscure titles, such as 18th-century agricultural guides in Africa or vintage biographies of 1950s car racers. Secondhand bookshop owners suspect these rare physical books are being acquired specifically because they lack digital footprints, offering fresh data for upcoming AI architectures.
