
Researchers publishing in Nature Communications on Thursday laid out a defence-in-depth framework for securing AI-driven biological sequence design, arguing that no single checkpoint can contain the dual-use risks as generative models move from data curation to DNA synthesis.
The paper arrives as governance recommendations in Nature Communications challenge the binary of open-versus-closed science.
The Bottom Line
- A team proposes screening AI-generated sequences at the synthesis stage by extending the International Gene Synthesis Consortium’s existing industry protocol, per the Nature Communications paper.
- Data governance becomes the bottleneck lever: funding mandates and data-sharing agreements are named as the most effective “upstream” instruments.
Five tiers, one pipeline
The core architectural move is data tiering. Building on a scheme from Bloomfield and colleagues, the paper sorts biological data into five biosecurity data levels, BDL-0 through BDL-4, ranked by the capability a model trained on that data could confer.
Open access remains for foundational data, while credentialed verification gates functional data related to pandemic pathogens, Nature reported. A proposed secure platform would host the restricted tiers, require user authentication and keep access logs to support investigations into problematic use.
| Level (per Bloomfield et al., cited in the paper) | Access posture described by the authors |
|---|---|
| BDL-0 | Open access for foundational data |
| BDL-1 to BDL-3 | Risk-stratified, proportionate controls |
| BDL-4 | Credentialed verification for functional pandemic-pathogen data |
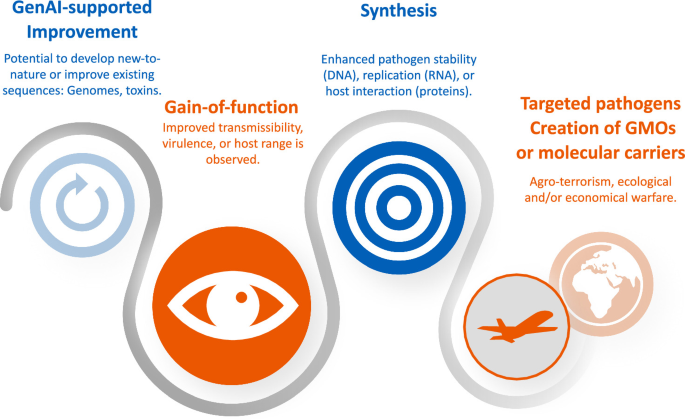
But the paper does not stop at data. It maps the risk chain across three domains — data, models and synthesis — and argues the mechanisms transfer between them.
Red-teaming and gated release, already standard for high-capability frontier models under protocols like the Frontier Model Forum’s, would be applied to biological sequence models before weights go public. Risk-scoring methods developed for datasets, the authors note, can be repurposed to score de novo sequences at the output end.
The fine-tuning loophole the authors flag
The vulnerability that motivates all this is concrete. Deep mutational scanning datasets for viral proteins can fine-tune foundation models to better predict immune-evading mutations, the paper states, citing published antigenic-escape modelling work. Automated design of enhanced human infectivity is not yet an established capability, the authors write — but the precedent shows how targeted fine-tuning injects specialised knowledge into general models.
The oversight problem compounds from there. Models such as Evo 1 and Evo 2 exclude eukaryote-infecting viral data from primary training sets, yet researchers can and do reintroduce it during downstream fine-tuning, Nature reported. Once those models are published openly, they lower the barrier to designing sequences with optimised pathogenic traits.
In governance terms, the safety decision made at training time can be undone after release — which is why the authors anchor their recommendations at institutional and funding layers rather than relying on researcher discretion alone.
Why the authors say governance can be a facilitator
The UK Biobank shows controlled access to sensitive genomic data improves standardisation and documentation while raising the resource’s utility. The IGSC’s industry-led screening framework for physical DNA orders demonstrates that the digital-to-biological bridge can carry standardised biosecurity checks. Institutional review processes and funding requirements already exist; the recommendations are designed to plug into them, minimising administrative friction.
The authors are candid about the limits. Risk classification is inherently difficult because an AI’s function is to identify patterns — restrictions risk being too broad or too narrow. Stringent rules could impede public-health research, erode scientific openness, fragment the research community into tiers, or bend to political pressure.
And well-organised malicious actors might build clandestine mirrors of classified datasets and models; at worst, the authors write, that could hand state actors developing biological weapons an advantage over defensive research.
What the market should price in
The paper calls for a multidisciplinary consensus group — modelled on bodies such as the German Research Foundation’s Joint Committee with the Leopoldina, the National Academies’ expert committees, or the WHO Advisory Group on Dual-Use Research of Concern — to reconcile existing risk classifications, including select-agent and export-control lists, into a shared international standard for what should not be openly available.
That consensus process carries its own disclosure risk the authors acknowledge: explicitly identifying sensitive data could hand malicious actors a roadmap to valuable datasets. Funding agencies incorporating biosecurity reviews into grant cycles — the paper’s fourth data recommendation — would convert voluntary practice into a de facto requirement for any lab needing public money.
The next observable step is organisational, not technical: whether the proposed international working group forms and agrees where the cutoff between open and tiered data should lie. The authors specify that the group must reconvene regularly to update classifications as capabilities advance — and that reaching consensus will be difficult, because stakeholders hold different views on which data types are sensitive.
