
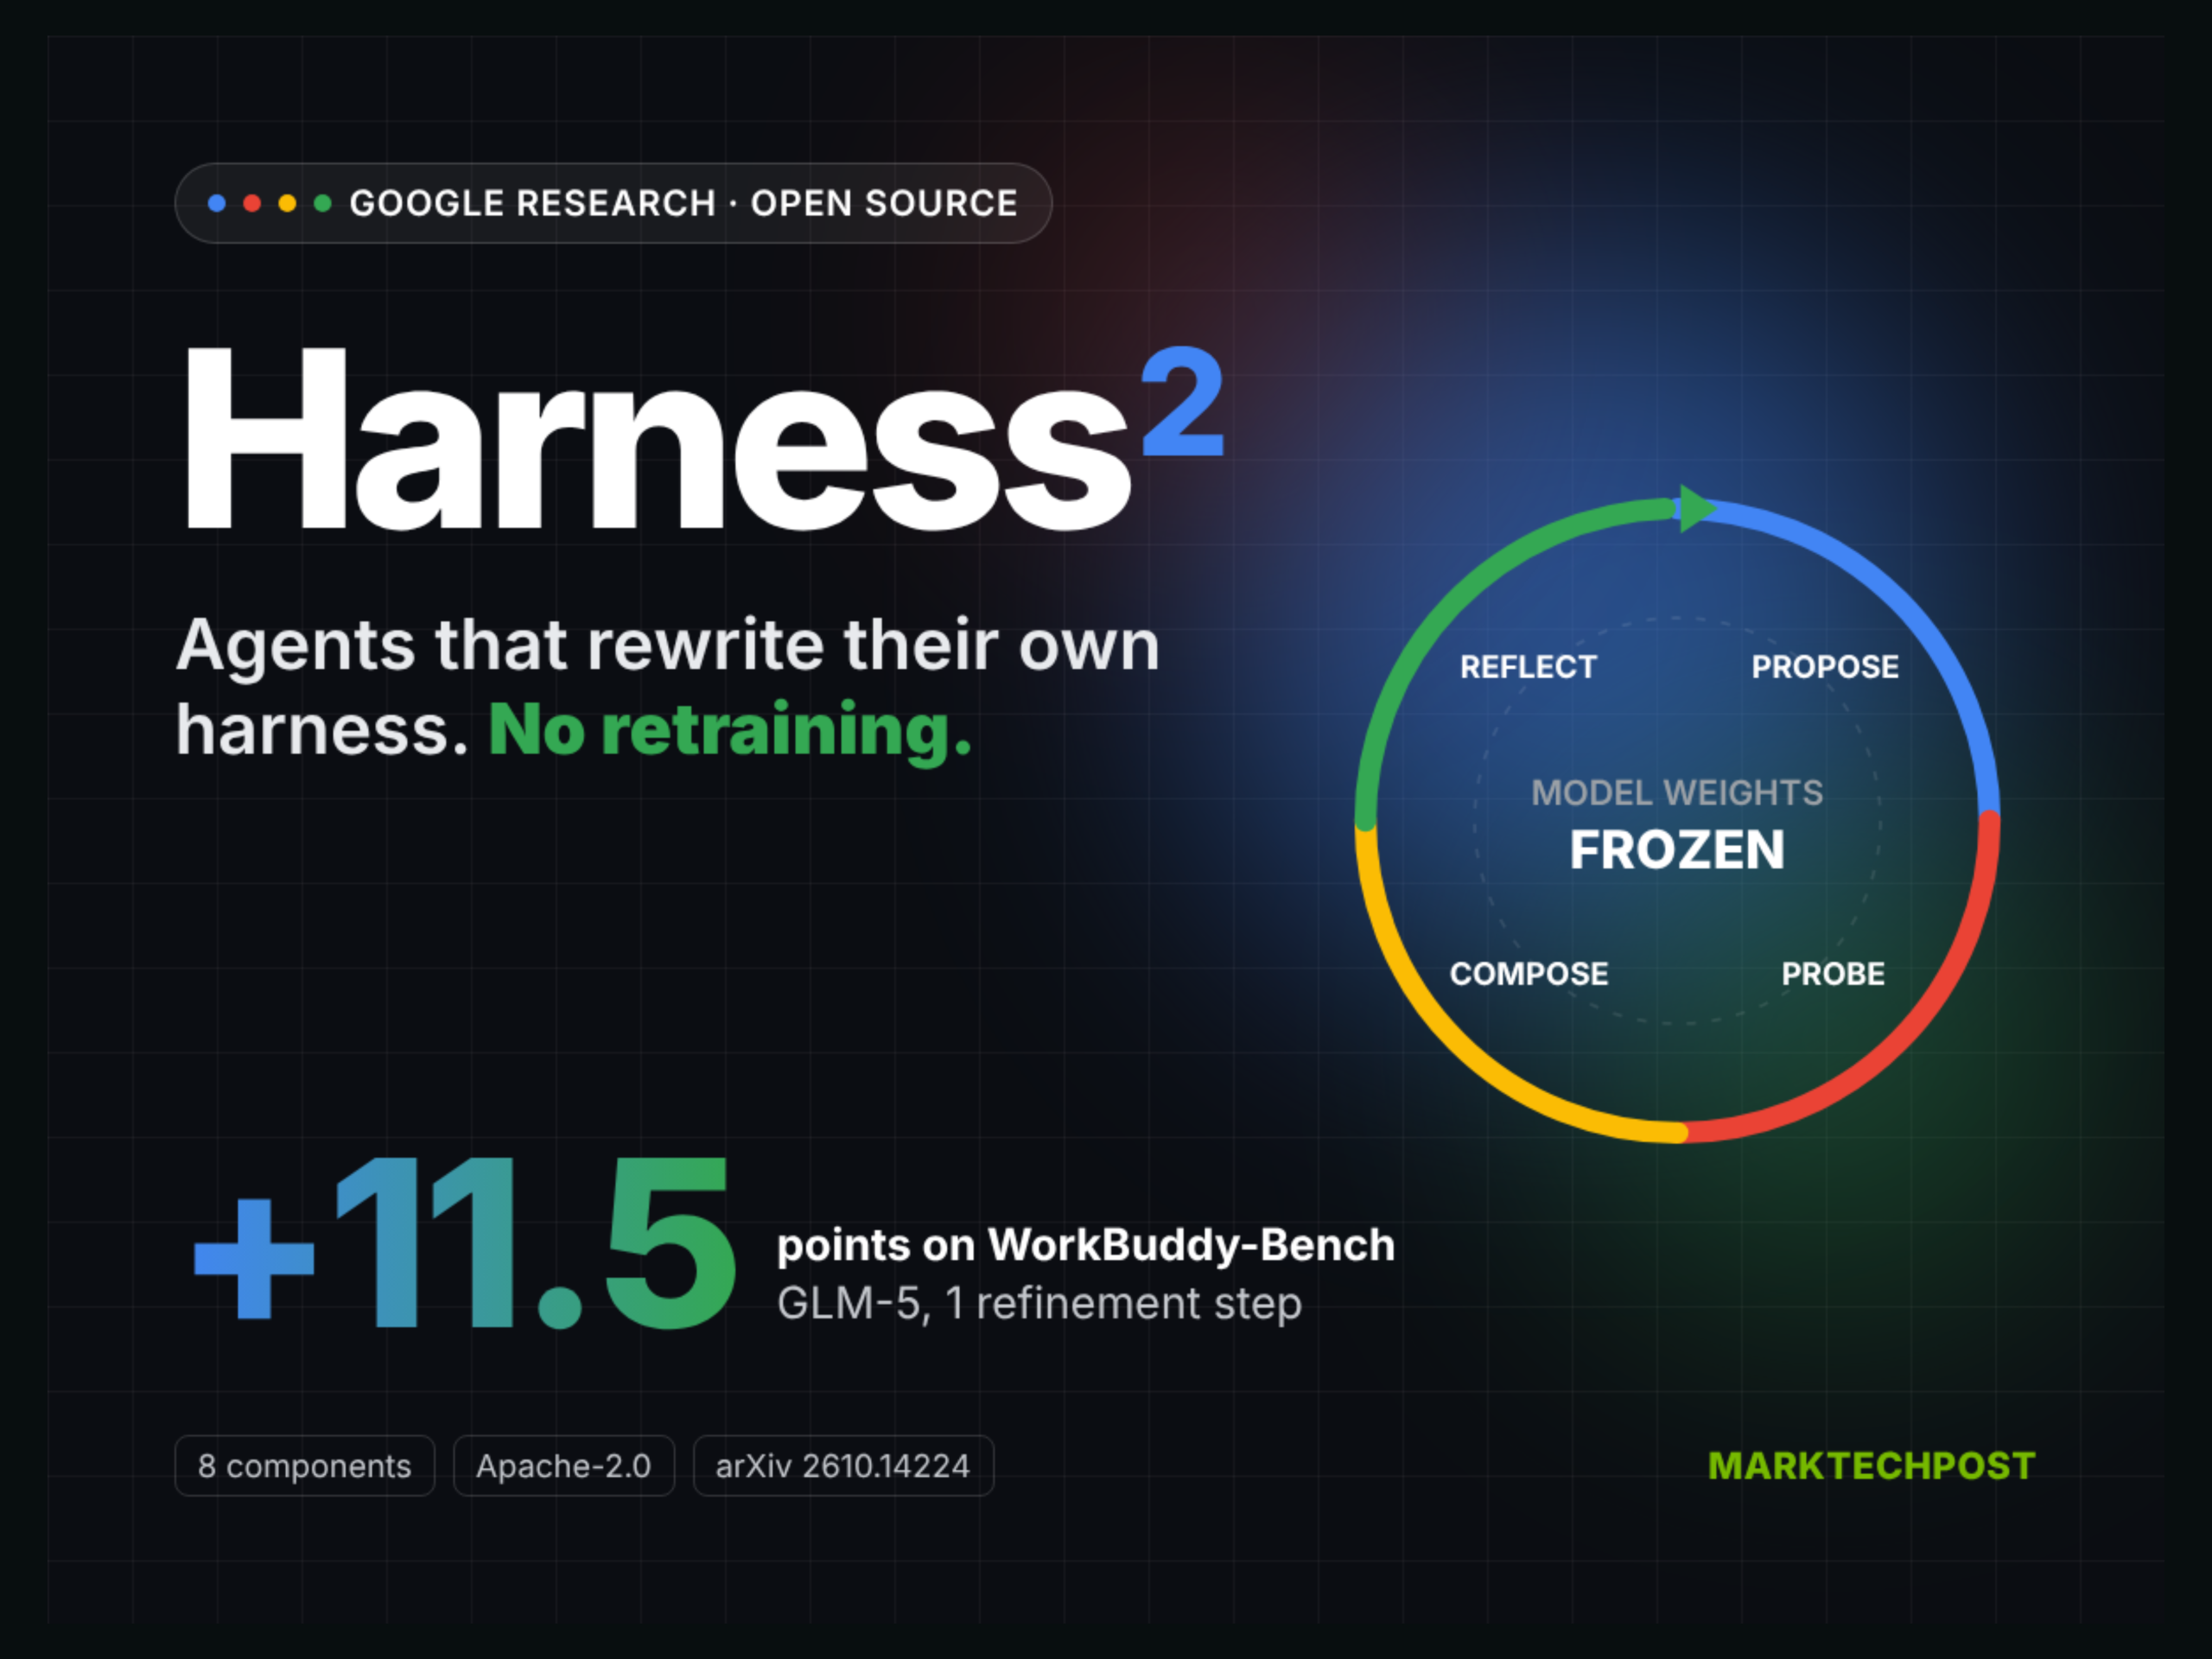
Google Cloud AI Research has open-sourced Harness², a version 0.1.0 recursive agent harnessing framework designed to optimize prompts, tools, memory, and orchestration layers around frozen foundation models during open-world deployment, as marktechpost.com reported this week.
How Recursive Agent Harnessing Bypasses Static Model Weights
Most self-improvement architectures rely heavily on access to ground-truth labels or static test cases during training phases. Harness² discards this assumption entirely, operating directly inside open-world environments where incoming tasks arrive completely unseen and lack automated verifiers. Instead of tweaking billions of underlying parameters, the framework focuses entirely on the 8 editable components that construct the runtime context around a frozen model. These components include system prompts, guardrails, memory structures, tool guidance, subagents, skills, executable scripts, and middleware plugins. By treating these elements as discrete, file-mounted modules, developers can systematically refine agent behavior without spending compute cycles on model weight updates.
The system executes optimization through two distinct tiers of recursion. Task-level recursion implements a contrastive Propose, Probe, Compose loop. First, the designated executor runs a target task once utilizing its base harness. An editor model then generates two competing candidates. The invariant candidate addresses generalized failures in planning or tool execution, while the domain candidate targets specific knowledge gaps for the current workflow. Both candidates process the same task simultaneously. A composer component evaluates their resulting execution trajectories against a reference trace, retaining only modifications that show demonstrable behavioral improvements.
Harnessing-level recursion takes over immediately after a task completes. A reflector module captures the newly adopted harness state along with an explicit lessons library file named EXPERIENCE.md. This persistent file guides subsequent proposal generation cycles. Every fresh task execution nonetheless originates cleanly from the baseline harness configuration. Scaling the search budget k dictates the execution depth, allowing developers to choose between running parallel probes across multiple candidates or chaining sequential refinement steps.
Installation requires a Linux environment running Python 3.12 or 3.13 alongside the uv package manager. Local demonstration runs proceed without requiring cloud model credentials by executing local rendering flags, whereas production model-backed deployments demand Node.js 20+, the Google Cloud CLI, and an active Vertex AI project configuration. Specialized benchmarks require extra external dependencies, such as Docker for WorkBuddy-Bench or Pandoc and Poppler for Harvey’s LAB.
Performance Benchmarks Across Professional Agent Workloads
Google Research evaluated the framework across three distinct professional evaluation suites: WorkBuddy-Bench, JobBench, and the partial scope of Harvey’s LAB. Test executors included Gemini 3.5 Flash and GLM-5 paired with different substrates such as OpenCode and Codex, using Claude Opus 4.8 as the default editor across three distinct experimental runs.
Empirical results demonstrate that weaker foundational executors extract significantly larger performance gains from the framework. A single refinement step successfully elevated GLM-5 configurations past baseline Gemini 3.5 Flash scores on WorkBuddy-Bench. For instance, GLM-5 running under OpenCode climbed from 64.2 to 75.7, marking an 11.5-point jump. In contrast, the same model paired with Codex gained a mere 1.2 points on JobBench, moving from 23.6 to 24.8. Scaling the parallel recursion budget to k=5 pushed Gemini under OpenCode to a peak score of 80.8 on WorkBuddy-Bench. Furthermore, three out of four tested setups utilized fewer total execution steps per task after applying the harness refinement, reducing operational loops.
When stacked against alternative harnessing methodologies like Meta-Harness, ReasoningBank, and standard Harness Scaling paradigms, Google’s framework distinguishes itself through its fully realized 8-component structure and its persistent cross-task lesson library. Developers looking to inspect the core architecture can review the foundational Harness² paper alongside prior work on Agentic Harness Engineering. Benchmark definitions and parameters are detailed further in the WorkBuddy-Bench evaluation spec and JobBench study.
