

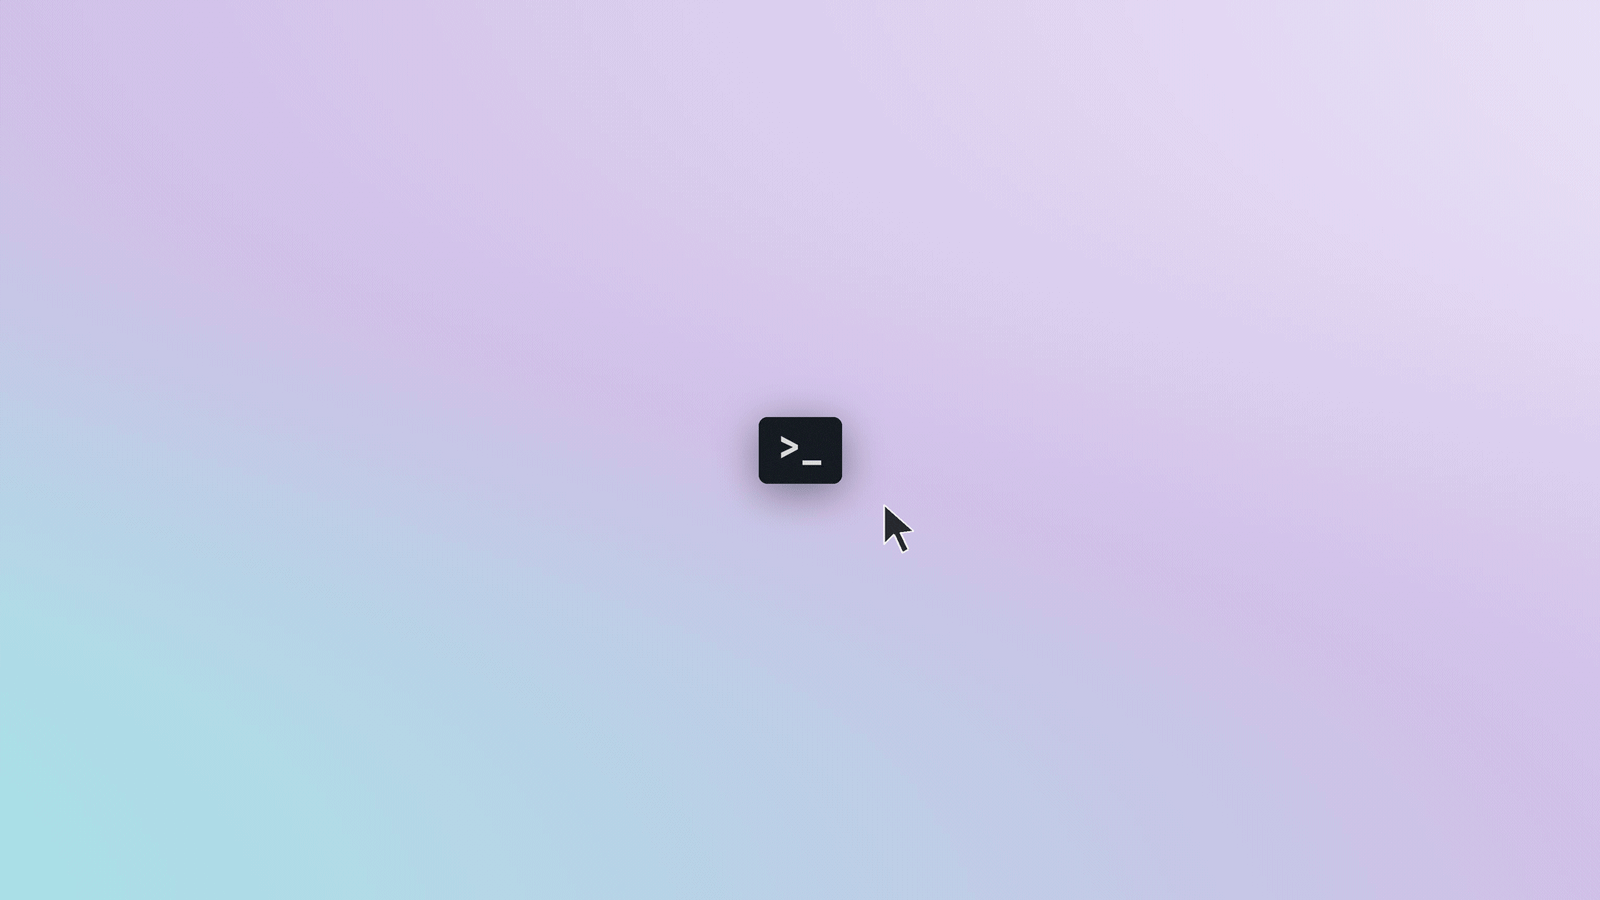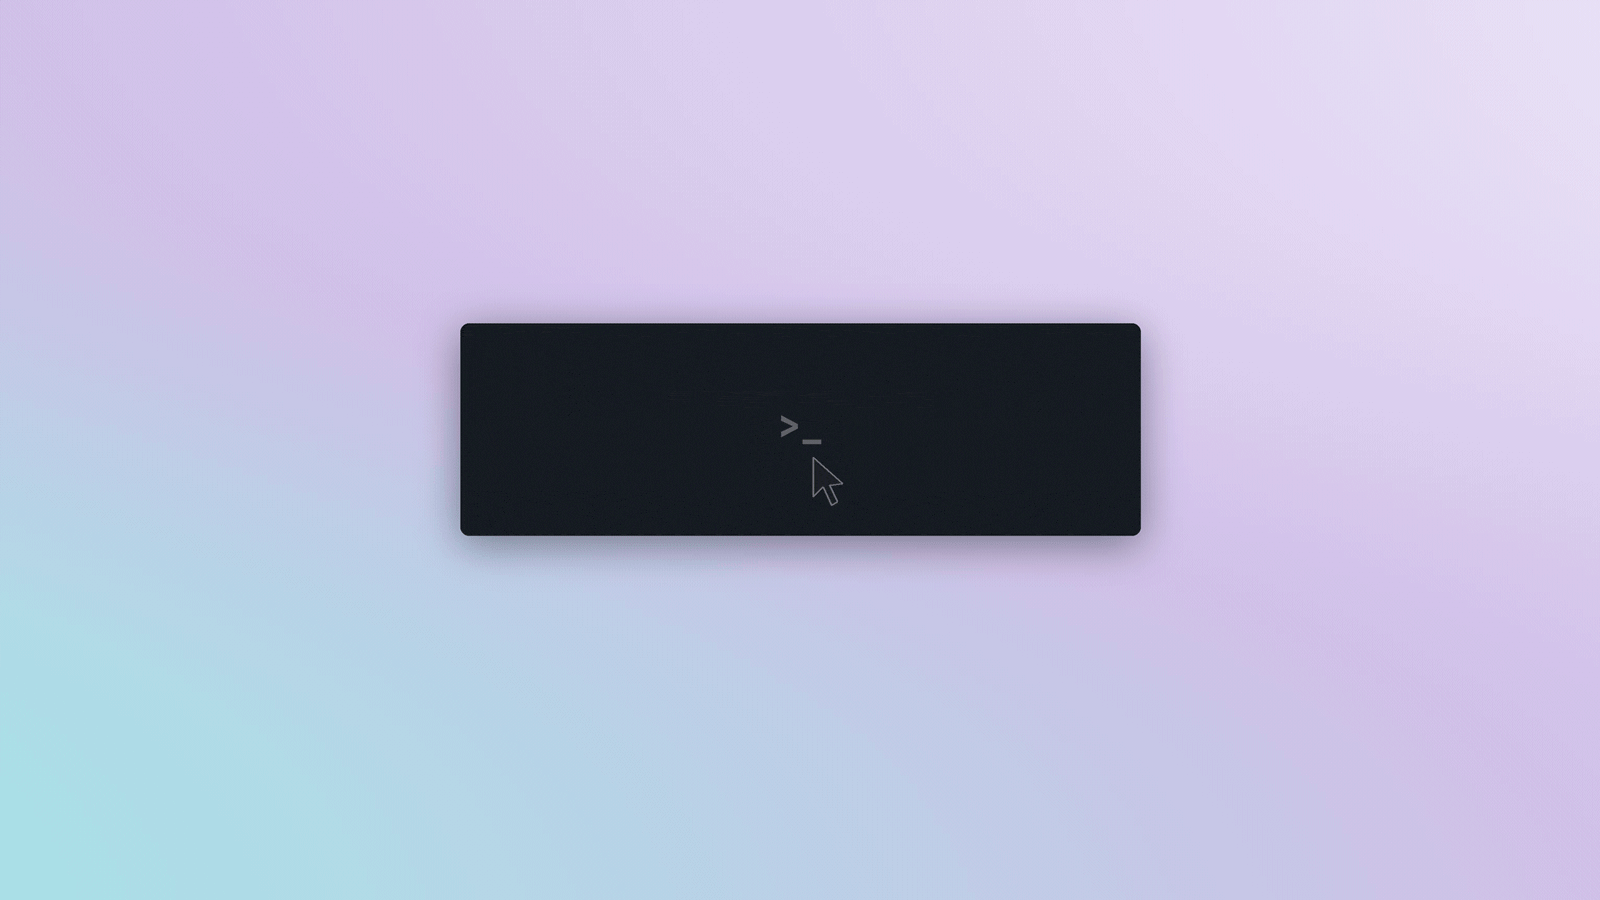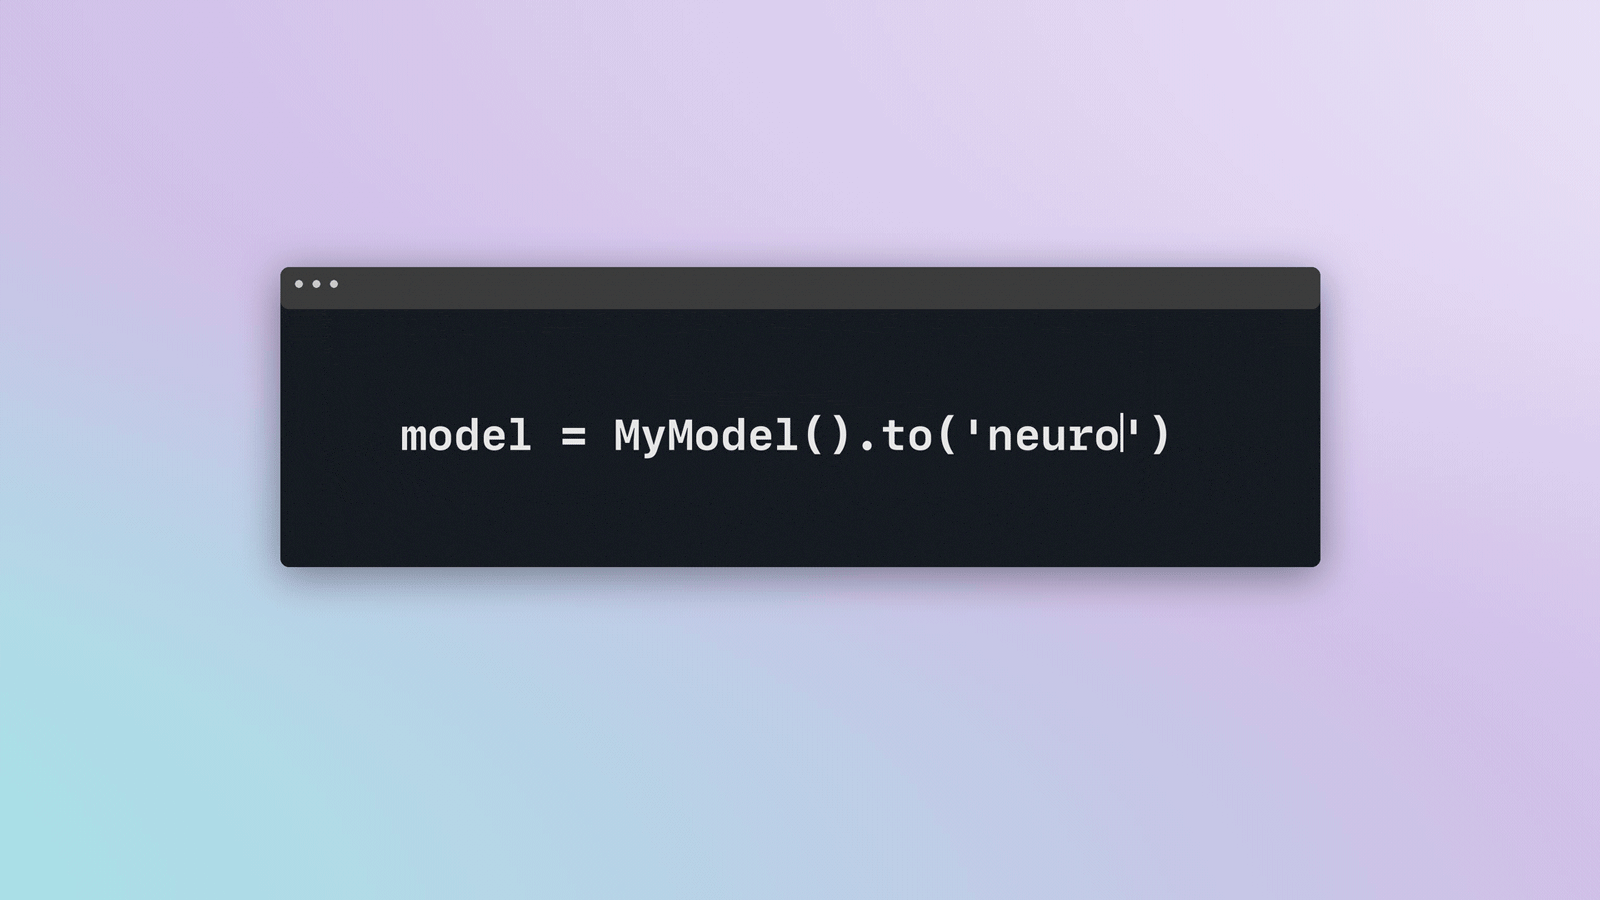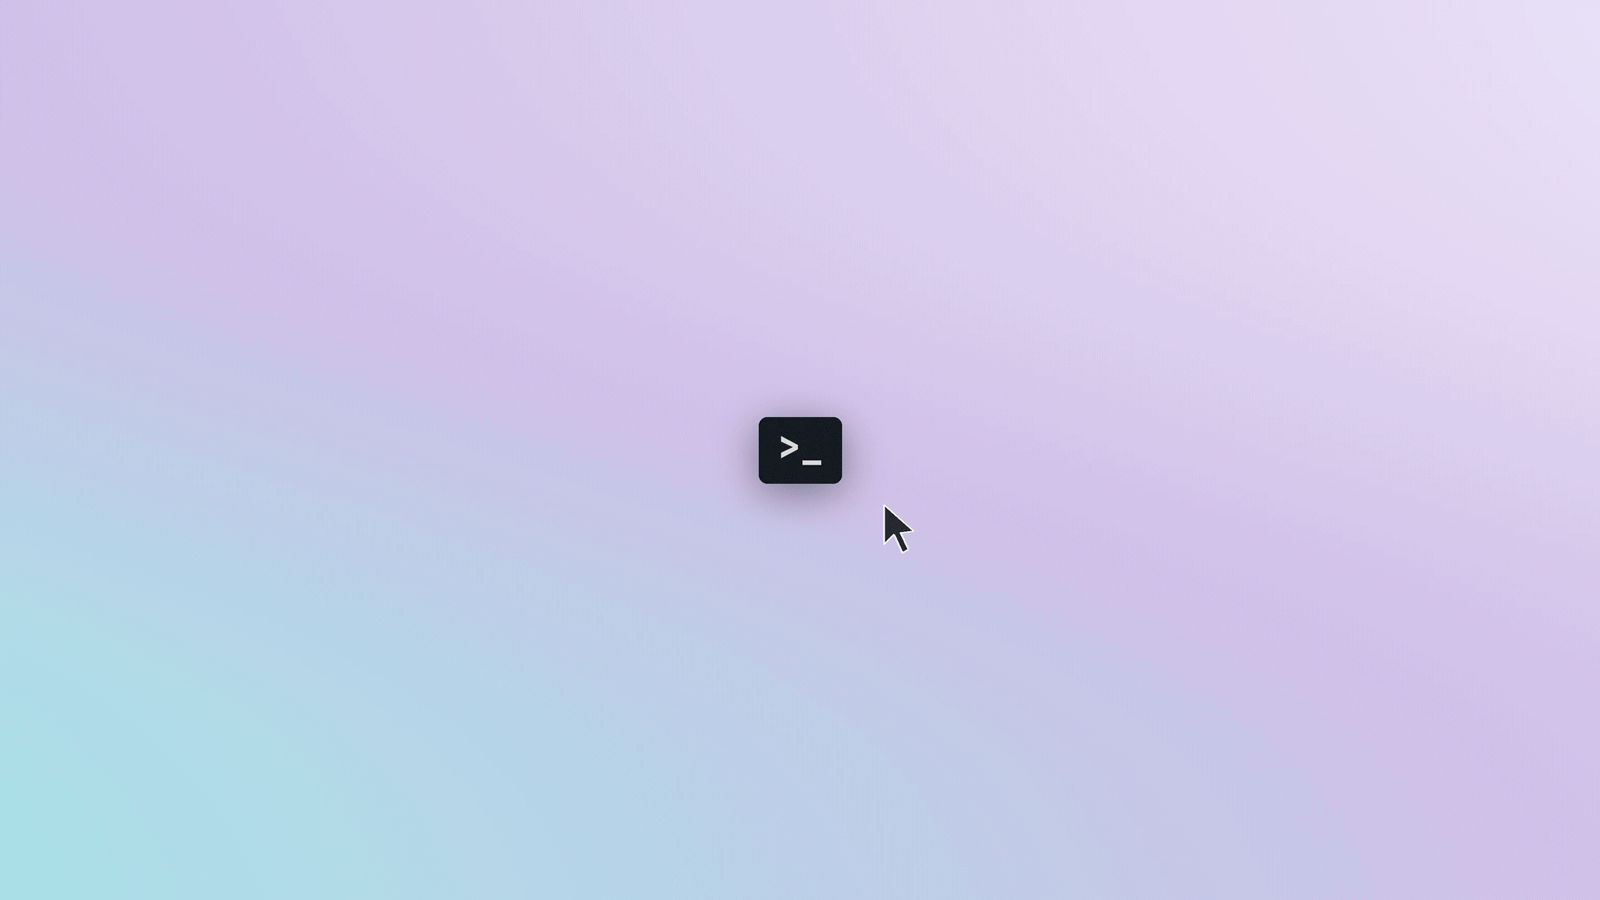
On Monday, October 19, 2026, Amazon.com, Inc. (NASDAQ: AMZN) web services unit AWS released TorchNeuron, a free, open-source software tool designed to let developers run AI applications built in PyTorch directly on custom Trainium chips with a single configuration change and no code rewrite required, challenging NVIDIA Corporation (NASDAQ: NVDA) and its proprietary CUDA software ecosystem.
The Bottom Line
- TorchNeuron removes the requirement to rewrite PyTorch code for Amazon’s Trainium chips, directly targeting the software moat that has made Nvidia the default hardware choice for AI developers.
- The tool’s release coincides with Amazon chip unit Annapurna Labs showcasing early traction among more than 30 customers, including voice AI provider Deepgram, which reported processing 70% more audio per dollar at production-grade accuracy.
- Beyond its own hardware, Amazon is contributing upstream code changes to the PyTorch project to remove chip-specific framework ties, seeking a hardware-agnostic developer ecosystem.
How TorchNeuron Targets Nvidia’s CUDA Software Moat
For more than a decade, Nvidia’s primary competitive advantage has not been silicon performance alone, but CUDA—the software infrastructure that allows applications written in frameworks like PyTorch to run on Nvidia GPUs. This deep software embedding has left competing hardware providers struggling to capture workloads because adapting existing code can require months of engineering work. Amazon’s TorchNeuron sits directly between PyTorch and the company’s custom Trainium chips, supporting existing codebases through a simple configuration modification.
According to Reuters, the software was announced ahead of a developer conference in Silicon Valley. Colin Brace, vice president of software for AWS Annapurna Labs, told Reuters in an interview that the move was aimed at reducing the friction AI developers face when trying in-house alternatives. This has been about meeting customers where they’re at,
Brace said.
Integration with AWS Infrastructure and Early Adopters
While PyTorch users can also port applications to AMD GPUs or Apple chips using basic configuration changes, Amazon argues that moving to Trainium provides direct access to the broader AWS cloud ecosystem. Amazon’s Annapurna Labs unit designed Trainium to handle both training and inference on a single platform. This integrated approach aims to deliver superior price-performance economics.

Among early adopters, voice AI provider Deepgram migrated to Trainium using native PyTorch support. AWS reported that Deepgram processes 70% more audio per dollar at production-grade accuracy. Additional enterprise and research implementations include Cartesia and the Lieber Institute for Brain Development, which uses biological, chemical, and language AI models for drug discovery via TorchNeuron on Trainium.
Upstream Code Contributions to PyTorch
Amazon’s strategy extends past hardware sales by altering the underlying framework itself. The company is contributing code changes directly to the main PyTorch project, working with the developer community to remove code that ties the framework to specific chips. This initiative aims to make PyTorch more hardware-agnostic.
Amazon CEO Andy Jassy reported in an annual shareholder letter that the company’s custom chip business, which includes Trainium and Graviton processors, held an annual revenue run rate exceeding $20 billion. By uncoupling PyTorch from Nvidia’s ecosystem, Amazon is attempting to lower the switching barriers that have historically preserved high margins for GPU vendors.
| Metric / Factor | Amazon Trainium / TorchNeuron Approach | Nvidia CUDA Ecosystem |
|---|---|---|
| Primary Software Interface | TorchNeuron (Open-source PyTorch extension) | CUDA proprietary software platform |
| Code Modification Required | Single configuration change (No rewrite) | Native optimization for GPU architecture |
| Workload Capability | Combined training and inference on one platform | Specialized GPU acceleration layers |
| Ecosystem Governance | Linux Foundation (PyTorch) + Upstream AWS contributions | Proprietary Nvidia stack |
Disclaimer: The information provided in this article is for educational and informational purposes only and does not constitute financial advice.
